Extended Data Figure 8: Cluster-level GP membership within each T cell lineage
Ziang Zhang
Last updated: 2026-08-27
Checks: 7 0
Knit directory:
immgenT-GP-analysis/analysis/
This reproducible R Markdown analysis was created with workflowr (version 1.7.2). The Checks tab describes the reproducibility checks that were applied when the results were created. The Past versions tab lists the development history.
Great! Since the R Markdown file has been committed to the Git repository, you know the exact version of the code that produced these results.
Great job! The global environment was empty. Objects defined in the global environment can affect the analysis in your R Markdown file in unknown ways. For reproduciblity it’s best to always run the code in an empty environment.
The command set.seed(1) was run prior to running the
code in the R Markdown file. Setting a seed ensures that any results
that rely on randomness, e.g. subsampling or permutations, are
reproducible.
Great job! Recording the operating system, R version, and package versions is critical for reproducibility.
Nice! There were no cached chunks for this analysis, so you can be confident that you successfully produced the results during this run.
Great job! Using relative paths to the files within your workflowr project makes it easier to run your code on other machines.
Great! You are using Git for version control. Tracking code development and connecting the code version to the results is critical for reproducibility.
The results in this page were generated with repository version 659ff00. See the Past versions tab to see a history of the changes made to the R Markdown and HTML files.
Note that you need to be careful to ensure that all relevant files for
the analysis have been committed to Git prior to generating the results
(you can use wflow_publish or
wflow_git_commit). workflowr only checks the R Markdown
file, but you know if there are other scripts or data files that it
depends on. Below is the status of the Git repository when the results
were generated:
Ignored files:
    Ignored:    .DS_Store
    Ignored:    .claude/
    Ignored:    analysis/.DS_Store
    Ignored:    analysis/.Rhistory
    Ignored:    analysis/assets/.DS_Store
    Ignored:    captions/
    Ignored:    code/.DS_Store
    Ignored:    code/other/topic_flashier_20250212.R
    Ignored:    code/other/topic_wrapper_20250215_alldata_backfit.sh
    Ignored:    data
    Ignored:    experiments/
    Ignored:    figures/.DS_Store
    Ignored:    figures/Previous/.DS_Store
    Ignored:    figures/Previous/bits/.DS_Store
    Ignored:    figures/Previous/bits/Figure 1/.DS_Store
    Ignored:    figures/Previous/bits/Figure 2/.DS_Store
    Ignored:    figures/Previous/bits/Figure 3/.DS_Store
    Ignored:    figures/Previous/bits/Figure 4/.DS_Store
    Ignored:    figures/Previous/bits/Figure 6/.DS_Store
    Ignored:    figures/Previous/bits/Figure 7/.DS_Store
    Ignored:    figures/Previous/bits/Figure S1/.DS_Store
    Ignored:    figures/Previous/bits/Figure S2/.DS_Store
    Ignored:    figures/Previous/bits/Figure S3/.DS_Store
    Ignored:    figures/Previous/bits/Figure S6/.DS_Store
    Ignored:    figures/Previous/bits/Figure S7/.DS_Store
    Ignored:    figures/final-selected/.DS_Store
    Ignored:    figures/final-selected/Figure 1/.DS_Store
    Ignored:    figures/final-selected/Figure 2/.DS_Store
    Ignored:    figures/final-selected/Figure 4/.DS_Store
    Ignored:    figures/final-selected/Figure S1/.DS_Store
    Ignored:    figures/final-selected/Figure S4/.DS_Store
    Ignored:    figures/templates_20260729/
    Ignored:    log/
    Ignored:    output/.DS_Store
    Ignored:    output/Figure2/
    Ignored:    output/Figure7b/7b_cell_metadata.csv.gz
    Ignored:    plan/
    Ignored:    tables/
    Ignored:    tmp/
Note that any generated files, e.g. HTML, png, CSS, etc., are not included in this status report because it is ok for generated content to have uncommitted changes.
These are the previous versions of the repository in which changes were
made to the R Markdown (analysis/FigureS8.Rmd) and HTML
(docs/FigureS8.html) files. If you’ve configured a remote
Git repository (see ?wflow_git_remote), click on the
hyperlinks in the table below to view the files as they were in that
past version.
| File | Version | Author | Date | Message |
|---|---|---|---|---|
| Rmd | 659ff00 | Ziang Zhang | 2026-08-27 | Extended Data Figure 8: per-lineage cluster structure plots |
All seven panels are produced by script/FigureS8.R.
They are the per-cluster, all-GP counterpart of Fig. 3B, which shows six hand-picked
lineage-defining GPs grouped by lineage: here every GP that marks a
sub-lineage cluster is shown, and cells are grouped by cluster within
each lineage. The GPs are selected from the cluster AUCs published as Extended Data Table 6, and script/verify_structure_plot_gps.R
re-derives every panel’s GP set from that published table, failing if it
disagrees with the panels or with the caption below. The code is shown
for reference (not re-executed on this page, since it loads the full
cell-by-GP loading matrix); the images are its pre-rendered output.
Setup
library(ggplot2)
library(ggrastr)
library(cowplot)
library(fastTopics) # structure_plot()

if (!file.exists("code/R/structure_plot_panels.R")) {
  stop("Run this script from the immgenT-GP-analysis repository root.")
}
source("code/R/structure_plot_panels.R")

data_path <- "data/"
figure_path <- "figures/final-selected/Figure S8/"
record_path <- "output/FigureS8/"
dir.create(figure_path, recursive = TRUE, showWarnings = FALSE)
dir.create(record_path, recursive = TRUE, showWarnings = FALSE)

# A figure script here was once seen to exit 0 with a complete log and write
# nothing at all (see script/README.md, "A re-run can silently not write"), so
# record when this run started and assert at the end that the panels are newer.
run_started_at <- Sys.time()
Panel definitions and GP selection
The panel map, the AUC threshold and the display filters live in
code/R/structure_plot_panels.R, which the verification
script reads as well, so the figure and the check cannot disagree about
what is shown:
# Panel letter per lineage, in panel order -- the level-1 lineage order of
# Figure 1D and Figure 3, with thymocytes and DP cells excluded as they are
# there. Both consumers iterate over the names of this map, so a lineage cannot
# be drawn, or checked, under another lineage's letter.
structure_plot_panels <- c(
  "CD8" = "s8a",
  "CD4" = "s8b",
  "Treg" = "s8c",
  "gdT" = "s8d",
  "CD8aa" = "s8e",
  "Tz" = "s8f",
  "DN" = "s8g"
)

# A GP is shown in a lineage's panel when its one-vs-rest AUC for predicting
# membership in at least one of that lineage's annotation_level2 clusters
# exceeds this threshold. Those AUCs are the values published as Extended Data
# Table 6 -- script/ExtendedDataTable6_GP_AUC_cluster.R reads the same file --
# which is what makes the two checkable against each other.
structure_plot_auc_threshold <- 0.9

# Display filters. These apply to the plotted cells only, never to the
# AUC-based GP selection above, which always uses every cluster of the lineage.
structure_plot_min_cluster_cells <- 100      # smaller clusters are not drawn
structure_plot_max_cells_per_cluster <- 2000 # larger clusters are subsampled
# ============================================================
# GP selection and the shared palette
# ============================================================
# Which lineage each cluster belongs to, from the metadata.
cluster_lineage <- cluster_lineage_map(level2_all, level1_all)
# verify_structure_plot_gps.R has only the published table to work from, so it
# maps clusters to lineages by their name prefix (CD8.A -> CD8) instead. Check
# that shortcut here, where the metadata-derived map is available, so the check
# cannot be re-deriving a different grouping than the figure drew.
auc_clusters <- rownames(auc_level2)
prefix_lineage <- sub("[.].*$", "", auc_clusters)
if (!identical(unname(cluster_lineage[auc_clusters]), prefix_lineage)) {
disagree <- auc_clusters[unname(cluster_lineage[auc_clusters]) != prefix_lineage]
stop(sprintf(
"cluster name prefixes disagree with annotation_level1 for: %s",
paste(disagree, collapse = ", ")
))
}
# One GP set per panel, and one color per GP over their union -- so a GP that
# marks clusters in two lineages keeps its color in both panels.
panel_gps <- gps_above_auc_by_lineage(auc_level2, cluster_lineage)
gp_colors <- structure_plot_gp_colors(unlist(panel_gps, use.names = FALSE))
message(sprintf(
"%d GPs over %d panels (AUC > %.1f): %s",
length(gp_colors), length(panel_gps), structure_plot_auc_threshold,
paste(sprintf("%s %d", names(panel_gps), lengths(panel_gps)), collapse = ", ")
))(a-g) Cluster-level GP membership by lineage
# ============================================================
# s8a-s8g: per-lineage structure plots
# ============================================================
# The loop iterates over the names of the panel map, so a lineage cannot be
# drawn under another lineage's letter.
cluster_records <- list()
gp_records <- list()

for (lineage in names(structure_plot_panels)) {
  panel <- structure_plot_panels[[lineage]]
  gps_lineage <- panel_gps[[lineage]]

  lineage_cells <- healthy_non_thymocyte[level1_all[healthy_non_thymocyte] == lineage]
  cluster_size <- table(droplevels(factor(level2_all[lineage_cells])))
  small_clusters <- names(cluster_size)[cluster_size < structure_plot_min_cluster_cells]
  lineage_cells <- lineage_cells[!level2_all[lineage_cells] %in% small_clusters]

  # Cap each cluster's width so one large cluster cannot crowd out the rest.
  set.seed(1234)
  keep <- unlist(lapply(
    split(seq_along(lineage_cells), level2_all[lineage_cells]),
    function(idx) {
      if (length(idx) > structure_plot_max_cells_per_cluster) {
        sample(idx, structure_plot_max_cells_per_cluster)
      } else {
        idx
      }
    }
  ))
  lineage_cells <- lineage_cells[keep]

  fit_lineage <- L_pm_filtered[lineage_cells, gps_lineage, drop = FALSE]
  grouping_lineage <- factor(level2_all[lineage_cells])

  # structure_plot() renames the colors it is given positionally, by the columns
  # of the matrix, so a palette in any other order would mislabel every bar.
  colors_lineage <- gp_colors[gps_lineage]
  if (!identical(names(colors_lineage), colnames(fit_lineage))) {
    stop(sprintf("panel %s: palette order does not match its GP columns.", panel))
  }

  set.seed(1234)
  p <- structure_plot(
    fit_lineage,
    topics = gps_lineage,
    gap = 40,
    n = 10000,
    colors = colors_lineage,
    grouping = grouping_lineage,
    ggplot_call = rasterized_structure_plot_call
  ) +
    labs(
      y = "membership",
      color = "",
      fill = "",
      title = sprintf(
        "%s (%d GPs, AUC > %.1f)",
        lineage,
        length(gps_lineage),
        structure_plot_auc_threshold
      )
    ) +
    guides(
      fill = guide_legend(ncol = 2),
      color = guide_legend(ncol = 2)
    ) +
    theme(
      plot.title = element_text(size = 11, face = "bold"),
      axis.text.x = element_text(size = 6, angle = 45, hjust = 1),
      axis.text.y = element_text(size = 9),
      axis.title = element_text(size = 10, face = "bold"),
      legend.position = "right",
      legend.key.size = unit(0.25, "cm"),
      legend.text = element_text(size = 5),
      legend.spacing.y = unit(0.02, "cm")
    )

  ggsave(
    filename = paste0(figure_path, panel, ".pdf"),
    plot = p,
    width = 11,
    height = 4,
    dpi = 300,
    limitsize = FALSE
  )

  # What this panel used, for the alignment check. Every cluster of the lineage
  # is listed, drawn or not: the GP selection above uses all of them.
  lineage_clusters <- sort(auc_clusters[prefix_lineage == lineage])
  drawn_size <- table(droplevels(factor(level2_all[lineage_cells])))
  cluster_records[[lineage]] <- data.frame(
    panel = panel,
    lineage = lineage,
    cluster = lineage_clusters,
    n_cells_healthy = as.integer(cluster_size[lineage_clusters]),
    n_cells_drawn = as.integer(ifelse(
      lineage_clusters %in% names(drawn_size),
      drawn_size[lineage_clusters],
      0L
    )),
    stringsAsFactors = FALSE
  )
  gp_records[[lineage]] <- data.frame(
    panel = panel,
    lineage = lineage,
    gp = gps_lineage,
    color = unname(gp_colors[gps_lineage]),
    max_auc_in_lineage = unname(apply(
      auc_level2[lineage_clusters, gps_lineage, drop = FALSE], 2,
      max, na.rm = TRUE
    )),
    stringsAsFactors = FALSE
  )
}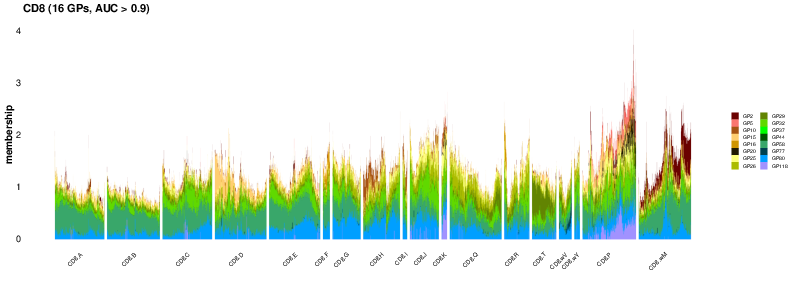
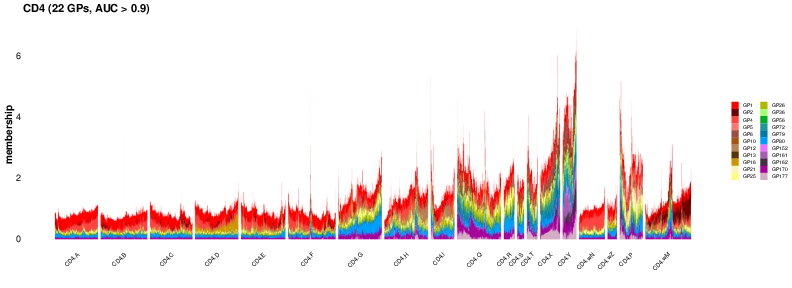
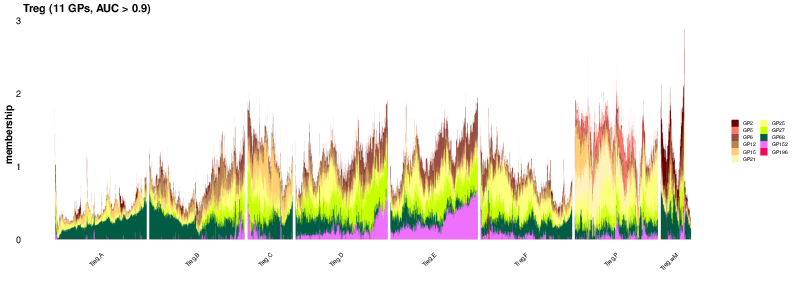
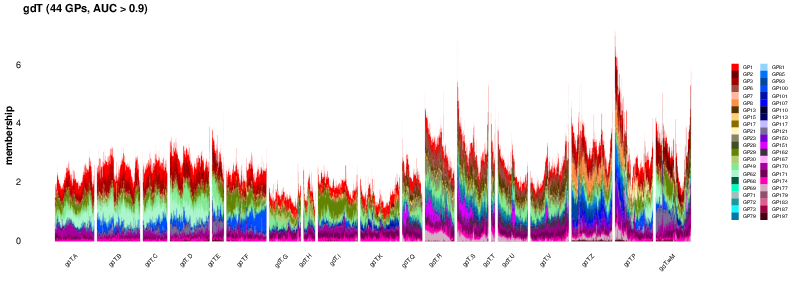
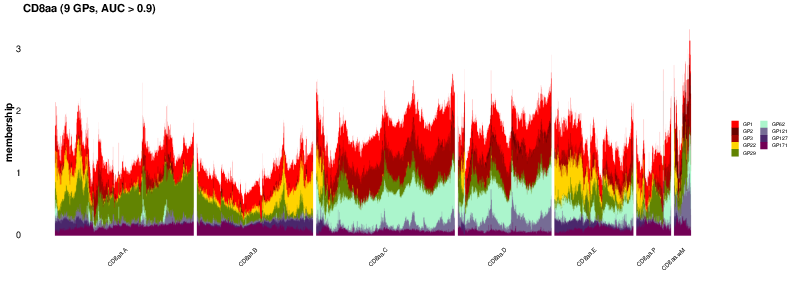
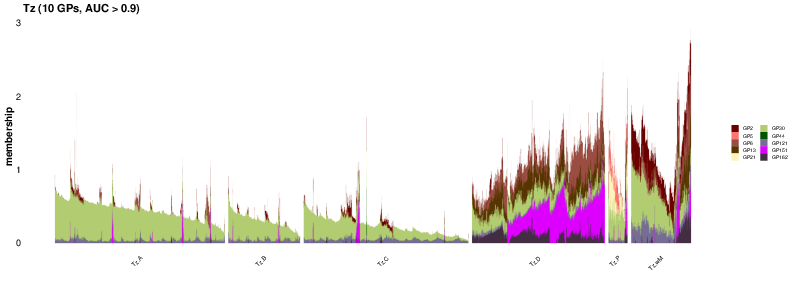
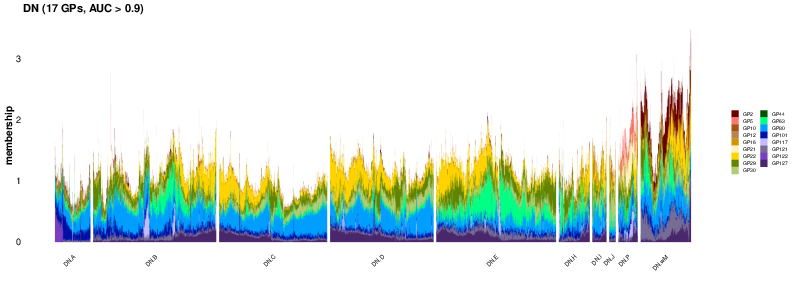
Extended Data Fig. 8a-g. Structure plots of
single-cell GP activity (membership / GP loading) in healthy
non-thymocyte cells, one panel per T cell lineage, with cells grouped by
sub-lineage cluster (annotation_level2): (a) CD8,
16 GPs; (b) CD4, 22 GPs; (c) Treg, 11 GPs; (d) gdT, 44 GPs; (e) CD8aa, 9
GPs; (f) Tz, 10 GPs; (g) DN, 17 GPs – 69 distinct GPs across
the seven panels. A GP is shown in a panel when its one-vs-rest AUC for
predicting membership in at least one cluster of that lineage, from the
GP’s loading, exceeds 0.9 (AUC > 0.9); those are the
values of Extended Data Table 6,
computed on the same healthy non-thymocyte cells. Selection uses all of
a lineage’s clusters, including any too small to draw. Each vertical bar
is one cell, partitioned among the GPs shown; bar height is that cell’s
total membership over those GPs and is not normalized, so it exceeds 1
where a cell loads on several of them. One color is assigned to each of
the 69 GPs and held fixed across panels, so a GP marking clusters in two
lineages reads the same in both. Within a cluster, cells are ordered by
a one-dimensional t-SNE of their memberships. Clusters with fewer than
100 cells are not drawn, larger clusters are subsampled to at most 2,000
cells, and at most 10,000 cells are drawn per panel – bar widths
therefore reflect the cells drawn rather than cluster size. Thymocytes
and DP cells are excluded, as in Fig. 3.
Record of what the panels drew
The GP sets, the palette, and the clusters each panel drew or omitted
are written out alongside the panels, which is what script/verify_structure_plot_gps.R
compares against Extended Data Table
6 and against the caption above:
# ============================================================
# What each panel drew, for the alignment check
# ============================================================
# script/verify_structure_plot_gps.R reads these two files, so that it can
# re-derive the panels' GP sets from the published Extended Data Table 6 without
# reloading the 1 GB loading matrix, and check the clusters drawn and omitted
# against the display filters above.
cluster_record <- do.call(rbind, cluster_records)
cluster_record$n_cells_healthy[is.na(cluster_record$n_cells_healthy)] <- 0L
write.csv(
  cluster_record,
  paste0(record_path, "s8_panel_clusters.csv"),
  row.names = FALSE
)
write.csv(
  do.call(rbind, gp_records),
  paste0(record_path, "s8_panel_gps.csv"),
  row.names = FALSE
)
sessionInfo()R version 4.5.1 (2025-06-13)
Platform: aarch64-apple-darwin20
Running under: macOS Sequoia 15.6.1
Matrix products: default
BLAS: /System/Library/Frameworks/Accelerate.framework/Versions/A/Frameworks/vecLib.framework/Versions/A/libBLAS.dylib
LAPACK: /Library/Frameworks/R.framework/Versions/4.5-arm64/Resources/lib/libRlapack.dylib; LAPACK version 3.12.1
locale:
[1] en_CA/en_CA/en_CA/C/en_CA/en_CA
time zone: America/Chicago
tzcode source: internal
attached base packages:
[1] stats graphics grDevices utils datasets methods base
loaded via a namespace (and not attached):
[1] vctrs_0.7.3 cli_3.6.6 knitr_1.50 rlang_1.2.0
[5] xfun_0.55 stringi_1.8.9 otel_0.2.0 promises_1.5.0
[9] jsonlite_2.0.0 workflowr_1.7.2 glue_1.8.1 rprojroot_2.1.1
[13] git2r_0.36.2 htmltools_0.5.9 httpuv_1.6.16 sass_0.4.10
[17] rmarkdown_2.30 evaluate_1.0.5 jquerylib_0.1.4 tibble_3.3.0
[21] fastmap_1.2.0 yaml_2.3.12 lifecycle_1.0.5 whisker_0.4.1
[25] stringr_1.6.0 compiler_4.5.1 fs_1.6.6 Rcpp_1.1.1-1.1
[29] pkgconfig_2.0.3 later_1.4.4 digest_0.6.39 R6_2.6.1
[33] pillar_1.11.1 magrittr_2.0.5 bslib_0.9.0 tools_4.5.1
[37] cachem_1.1.0