Biostatistical analysis part 2
AGC
2 2 2022
Last updated: 2022-06-22
Checks: 7 0
Knit directory: scSeq_Hefendehl/
This reproducible R Markdown analysis was created with workflowr (version 1.7.0). The Checks tab describes the reproducibility checks that were applied when the results were created. The Past versions tab lists the development history.
Great! Since the R Markdown file has been committed to the Git repository, you know the exact version of the code that produced these results.
Great job! The global environment was empty. Objects defined in the global environment can affect the analysis in your R Markdown file in unknown ways. For reproduciblity it’s best to always run the code in an empty environment.
The command set.seed(20220131) was run prior to running
the code in the R Markdown file. Setting a seed ensures that any results
that rely on randomness, e.g. subsampling or permutations, are
reproducible.
Great job! Recording the operating system, R version, and package versions is critical for reproducibility.
Nice! There were no cached chunks for this analysis, so you can be confident that you successfully produced the results during this run.
Great job! Using relative paths to the files within your workflowr project makes it easier to run your code on other machines.
Great! You are using Git for version control. Tracking code development and connecting the code version to the results is critical for reproducibility.
The results in this page were generated with repository version cfbfcf6. See the Past versions tab to see a history of the changes made to the R Markdown and HTML files.
Note that you need to be careful to ensure that all relevant files for
the analysis have been committed to Git prior to generating the results
(you can use wflow_publish or
wflow_git_commit). workflowr only checks the R Markdown
file, but you know if there are other scripts or data files that it
depends on. Below is the status of the Git repository when the results
were generated:
Ignored files:
    Ignored:    .DS_Store
    Ignored:    .Rhistory
    Ignored:    .Rproj.user/
    Ignored:    analysis/.Rhistory
    Ignored:    data/ReloadAllData_Hefendehl_Stroke_Dec'21.RData
    Ignored:    data/Sample_Tables/
    Ignored:    data/counts.csv
    Ignored:    data/genecounts.csv
    Ignored:    data/microglia_protein.rds
    Ignored:    data/samples.integrated.RData
    Ignored:    data/tx2genes.csv
    Ignored:    output/Descriptives.Rmd
    Ignored:    output/Descriptives.docx

Untracked files:
    Untracked:  geneviewer/Dataset.RData
    Untracked:  workflow_helper.R

Unstaged changes:
    Modified:   .Rprofile
    Modified:   .gitattributes
    Modified:   .gitignore
    Modified:   README.md
    Modified:   _workflowr.yml
    Modified:   data/README.md
    Modified:   geneviewer/app.R
    Modified:   geneviewer/rsconnect/shinyapps.io/molgenlab/geneviewer.dcf
    Modified:   output/README.md
    Modified:   scSeq_Hefendehl.Rproj
Note that any generated files, e.g. HTML, png, CSS, etc., are not included in this status report because it is ok for generated content to have uncommitted changes.
These are the previous versions of the repository in which changes were
made to the R Markdown (analysis/01_Biostat.Rmd) and HTML
(docs/01_Biostat.html) files. If you’ve configured a remote
Git repository (see ?wflow_git_remote), click on the
hyperlinks in the table below to view the files as they were in that
past version.
| File | Version | Author | Date | Message |
|---|---|---|---|---|
| Rmd | cfbfcf6 | achiocch | 2022-06-22 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | cfbfcf6 | achiocch | 2022-06-22 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | faf20e9 | achiocch | 2022-05-16 | Build site. |
| Rmd | 8791434 | achiocch | 2022-05-16 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 8791434 | achiocch | 2022-05-16 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 51b35c8 | achiocch | 2022-04-26 | Build site. |
| Rmd | 3277c08 | achiocch | 2022-04-26 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 41d6cd0 | achiocch | 2022-04-26 | Build site. |
| Rmd | 7d20262 | achiocch | 2022-04-26 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| Rmd | 8e44cfc | achiocch | 2022-04-22 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 8e44cfc | achiocch | 2022-04-22 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 9b778b1 | achiocch | 2022-04-19 | Build site. |
| Rmd | d2ed458 | achiocch | 2022-04-19 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | d2ed458 | achiocch | 2022-04-19 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 55b3c82 | achiocch | 2022-04-08 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | cf395f4 | achiocch | 2022-03-30 | Build site. |
| Rmd | 55e7738 | achiocch | 2022-03-30 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 55e7738 | achiocch | 2022-03-30 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | c998828 | achiocch | 2022-03-30 | Build site. |
| Rmd | f21fdf7 | achiocch | 2022-03-30 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | f21fdf7 | achiocch | 2022-03-30 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 87439a3 | achiocch | 2022-02-21 | Build site. |
| Rmd | ef56d05 | achiocch | 2022-02-21 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | d6f2105 | achiocch | 2022-02-21 | Build site. |
| Rmd | b832d1c | achiocch | 2022-02-21 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| Rmd | 95fb700 | achiocch | 2022-02-21 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 95fb700 | achiocch | 2022-02-21 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 79dd0b1 | achiocch | 2022-02-21 | Build site. |
| Rmd | 73aabec | achiocch | 2022-02-21 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | ded601d | achiocch | 2022-02-03 | Build site. |
| Rmd | 858d646 | achiocch | 2022-02-03 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 858d646 | achiocch | 2022-02-03 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 50fe211 | achiocch | 2022-02-03 | Build site. |
| Rmd | 64cd37c | achiocch | 2022-02-03 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 5fbdba4 | achiocch | 2022-02-02 | Build site. |
| Rmd | 636a117 | achiocch | 2022-02-02 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| html | 636a117 | achiocch | 2022-02-02 | wflow_publish(c("analysis/", "docs/", "code/*")) |
| Rmd | 9044798 | Andreas Geburtig-Chiocchetti | 2022-02-02 | workflowr automated |
| Rmd | 57c9e70 | achiocch | 2022-02-02 | adds initial html files |
| html | 57c9e70 | achiocch | 2022-02-02 | adds initial html files |
| Rmd | ddb6373 | achiocch | 2022-02-02 | first commit |
#get sample data
samples.integrated@meta.data %>% as.data.frame() -> samplemeta

# convert to correct data type

# define genotype as is
samplemeta$Genotype_corr = factor(samplemeta$Genotype=="wt", levels=c(F,T), labels = c("APPPS1+", "WT"))
samplemeta$Genotype_corr = relevel(samplemeta$Genotype_corr, ref="WT")

samplemeta$methoxy = factor(samplemeta$Genotype=="MX04+", levels=c(T,F), labels = c("MX04+", "MX04-"))

samplemeta$Treatment = as.factor(samplemeta$Treatment)
samplemeta$Treatment = relevel(samplemeta$Treatment, ref="Ctrl")
samplemeta$Mouse_ID = as.factor(samplemeta$Mouse_ID)
samplemeta$Sex = as.factor(samplemeta$Sex)
samplemeta$Brain_region = as.factor(samplemeta$Brain_region)
samplemeta$Celltype = as.factor(samplemeta$Celltype)

nCells=nrow(samplemeta)
nMice=nlevels(samplemeta$Mouse_ID)
nCelltypes=nlevels(samplemeta$Celltype)
Sample descriptive:
Data contains a total of 649 Cells from 9. Q: Original raw datset containing only frankfurt data included 1149 cells. What were the filter criteria in the primary cell type analysis
Cells per Mouse
Cells per Strain
table(Mouse_ID=samplemeta$Mouse_ID) %>% as.data.frame() %>% display_tab()Cells per Genotype
table(Genotype=samplemeta$Genotype_corr, Treatment=samplemeta$Treatment) %>% as.data.frame() %>% display_tab()table(Genotype=samplemeta$Genotype_corr, Celltype=samplemeta$Celltype) %>%
as.data.frame() %>% display_tab()table(Genotype=samplemeta$Genotype_corr,
Celltype=samplemeta$Celltype, Treatment=samplemeta$Treatment
) %>%
as.data.frame() %>% display_tab()samplemeta$condition=paste0(samplemeta$Genotype_corr,"_", samplemeta$Treatment)
variables=c("Celltype","Sex", "Age","Genotype_corr", "Treatment", "condition","Phase", "Brain_region","nCount_RNA","pseudoaligned_reads", "percent.mito", "percent.ribo", "Mouse_ID")Descriptive stats across Cell type
res = compareGroups(Celltype~., data = samplemeta[,variables], max.ylev = 10)
#summary(res)
export_table <- createTable(res)
options(width = 10000)
export2md(export_table)| T/NK | Microglia_0 | Microglia_1 | Microglia_2 | Microglia_3 | Microglia_4 | Microglia_5 | Granulocytes | p.overall | |
|---|---|---|---|---|---|---|---|---|---|
| N=22 | N=186 | N=164 | N=107 | N=99 | N=26 | N=23 | N=22 | ||
| Sex: | . | ||||||||
| f | 6 (27.3%) | 27 (14.5%) | 21 (12.8%) | 11 (10.3%) | 11 (11.1%) | 1 (3.85%) | 2 (8.70%) | 8 (36.4%) | |
| m | 16 (72.7%) | 159 (85.5%) | 143 (87.2%) | 96 (89.7%) | 88 (88.9%) | 25 (96.2%) | 21 (91.3%) | 14 (63.6%) | |
| Age: | <0.001 | ||||||||
| 10 | 13 (59.1%) | 65 (34.9%) | 35 (21.3%) | 26 (24.3%) | 32 (32.3%) | 6 (23.1%) | 12 (52.2%) | 9 (40.9%) | |
| 17 | 1 (4.55%) | 19 (10.2%) | 68 (41.5%) | 31 (29.0%) | 29 (29.3%) | 11 (42.3%) | 3 (13.0%) | 0 (0.00%) | |
| 9 | 8 (36.4%) | 102 (54.8%) | 61 (37.2%) | 50 (46.7%) | 38 (38.4%) | 9 (34.6%) | 8 (34.8%) | 13 (59.1%) | |
| Genotype_corr: | <0.001 | ||||||||
| WT | 3 (13.6%) | 66 (35.5%) | 93 (56.7%) | 51 (47.7%) | 44 (44.4%) | 15 (57.7%) | 11 (47.8%) | 6 (27.3%) | |
| APPPS1+ | 19 (86.4%) | 120 (64.5%) | 71 (43.3%) | 56 (52.3%) | 55 (55.6%) | 11 (42.3%) | 12 (52.2%) | 16 (72.7%) | |
| Treatment: | <0.001 | ||||||||
| Ctrl | 3 (13.6%) | 101 (54.3%) | 113 (68.9%) | 70 (65.4%) | 68 (68.7%) | 21 (80.8%) | 12 (52.2%) | 2 (9.09%) | |
| Stroke | 19 (86.4%) | 85 (45.7%) | 51 (31.1%) | 37 (34.6%) | 31 (31.3%) | 5 (19.2%) | 11 (47.8%) | 20 (90.9%) | |
| condition: | . | ||||||||
| APPPS1+_Ctrl | 2 (9.09%) | 82 (44.1%) | 45 (27.4%) | 39 (36.4%) | 39 (39.4%) | 10 (38.5%) | 9 (39.1%) | 2 (9.09%) | |
| APPPS1+_Stroke | 17 (77.3%) | 38 (20.4%) | 26 (15.9%) | 17 (15.9%) | 16 (16.2%) | 1 (3.85%) | 3 (13.0%) | 14 (63.6%) | |
| WT_Ctrl | 1 (4.55%) | 19 (10.2%) | 68 (41.5%) | 31 (29.0%) | 29 (29.3%) | 11 (42.3%) | 3 (13.0%) | 0 (0.00%) | |
| WT_Stroke | 2 (9.09%) | 47 (25.3%) | 25 (15.2%) | 20 (18.7%) | 15 (15.2%) | 4 (15.4%) | 8 (34.8%) | 6 (27.3%) | |
| Phase: | 0.002 | ||||||||
| G1 | 1 (4.55%) | 79 (42.5%) | 70 (42.7%) | 59 (55.1%) | 42 (42.4%) | 12 (46.2%) | 14 (60.9%) | 5 (22.7%) | |
| G2M | 11 (50.0%) | 50 (26.9%) | 38 (23.2%) | 17 (15.9%) | 21 (21.2%) | 6 (23.1%) | 4 (17.4%) | 11 (50.0%) | |
| S | 10 (45.5%) | 57 (30.6%) | 56 (34.1%) | 31 (29.0%) | 36 (36.4%) | 8 (30.8%) | 5 (21.7%) | 6 (27.3%) | |
| Brain_region: | <0.001 | ||||||||
| Cortex | 3 (13.6%) | 101 (54.3%) | 113 (68.9%) | 70 (65.4%) | 68 (68.7%) | 21 (80.8%) | 12 (52.2%) | 2 (9.09%) | |
| Lesion | 19 (86.4%) | 85 (45.7%) | 51 (31.1%) | 37 (34.6%) | 31 (31.3%) | 5 (19.2%) | 11 (47.8%) | 20 (90.9%) | |
| nCount_RNA | 164049 (80916) | 150451 (78955) | 134224 (54802) | 170420 (76702) | 152640 (72678) | 172200 (70772) | 176087 (64299) | 144828 (65899) | 0.002 |
| pseudoaligned_reads | 165078 (81748) | 150942 (78850) | 134355 (54810) | 170750 (76639) | 152790 (72668) | 172433 (70717) | 176390 (64225) | 145316 (65972) | 0.002 |
| percent.mito | 2.23 (0.90) | 1.75 (1.17) | 1.62 (1.01) | 2.07 (1.07) | 1.72 (1.15) | 1.97 (1.02) | 2.11 (0.77) | 0.92 (1.00) | <0.001 |
| percent.ribo | 6.53 (2.72) | 2.68 (1.58) | 2.75 (1.81) | 2.44 (1.24) | 3.28 (1.67) | 2.11 (0.85) | 2.91 (1.35) | 2.01 (1.17) | <0.001 |
| Mouse_ID: | . | ||||||||
| 23#15773 | 0 (0.00%) | 7 (3.76%) | 25 (15.2%) | 12 (11.2%) | 17 (17.2%) | 4 (15.4%) | 1 (4.35%) | 0 (0.00%) | |
| 23#15774 | 0 (0.00%) | 1 (0.54%) | 30 (18.3%) | 10 (9.35%) | 6 (6.06%) | 1 (3.85%) | 1 (4.35%) | 0 (0.00%) | |
| 23#15792 | 1 (4.55%) | 11 (5.91%) | 13 (7.93%) | 9 (8.41%) | 6 (6.06%) | 6 (23.1%) | 1 (4.35%) | 0 (0.00%) | |
| 386 | 1 (4.55%) | 14 (7.53%) | 9 (5.49%) | 2 (1.87%) | 6 (6.06%) | 1 (3.85%) | 5 (21.7%) | 3 (13.6%) | |
| 387 | 11 (50.0%) | 10 (5.38%) | 5 (3.05%) | 6 (5.61%) | 5 (5.05%) | 0 (0.00%) | 1 (4.35%) | 6 (27.3%) | |
| 388 | 1 (4.55%) | 41 (22.0%) | 21 (12.8%) | 18 (16.8%) | 21 (21.2%) | 5 (19.2%) | 6 (26.1%) | 0 (0.00%) | |
| 409 | 1 (4.55%) | 33 (17.7%) | 16 (9.76%) | 18 (16.8%) | 9 (9.09%) | 3 (11.5%) | 3 (13.0%) | 3 (13.6%) | |
| 457 | 1 (4.55%) | 41 (22.0%) | 24 (14.6%) | 21 (19.6%) | 18 (18.2%) | 5 (19.2%) | 3 (13.0%) | 2 (9.09%) | |
| 461 | 6 (27.3%) | 28 (15.1%) | 21 (12.8%) | 11 (10.3%) | 11 (11.1%) | 1 (3.85%) | 2 (8.70%) | 8 (36.4%) |
export2xls(export_table,paste0(home,"/docs/Descriptives.xlsx"))download data as excel file here
Preprocessing
include only genes that are different across samples (5 974 excluded) include only genes with more than 10 reads in at least 10 cells in at least one Celltype (21 733 transcripts excluded) exclude all cells with less than 10000 reads (none excluded)
649 cells and 11 623 transcripts analyzed
#get normalized counts
# question to Desiree hat the Seurat object been initialized with normalized data?
counts <- samples.integrated@assays$RNA@counts %>% as.data.frame()

# drop no variance data and sort by samplemeta
counts <- counts[apply(counts,1, sd) > 0, rownames(samplemeta)]

# drop genes with low detection rate (more than 5 counts per cell)
counts_per_celltype=apply(counts, 1, function(x){tapply(x, samplemeta$Celltype, function(z){sum(z>10,na.rm=T)})}) %>% as.data.frame()

# keep RNAs with at least 10 cells with good expression
idxr=which(colSums(counts_per_celltype)>10)

idxc=which(colSums(counts)>10000)

counts = counts[idxr,idxc]
samplemeta=samplemeta[colnames(counts), ]
Overview tables
samplemeta$corrGenotype_Treatment<-
  paste0(samplemeta$Genotype_corr," ", samplemeta$Treatment)

sumstat = counts %>% t() %>%
  aggregate(by=samplemeta["corrGenotype_Treatment"], median) %>%
  t() %>% as.data.frame()

names(sumstat) <- paste0("median",sumstat[1,])
sumstat<-sumstat[-1,]

sumstatCelltype = counts %>% t() %>%
  aggregate(by=samplemeta["Celltype"], median) %>%
  t() %>% as.data.frame()

names(sumstatCelltype) <- paste0("median",sumstatCelltype[1,])
sumstatCelltype<-sumstatCelltype[-1,]


Geno.Treatment_kruskal=apply(counts,1, function(x){
  res = kruskal.test(unlist(x)~samplemeta$corrGenotype_Treatment) %>% unlist()
  return(as.numeric(res["p.value"]))
})

Geno.Treatment_kruskal_fdr = p.adjust(Geno.Treatment_kruskal, method = "fdr")

Celltype_kruskal=apply(counts,1, function(x){
   res = kruskal.test(unlist(x)~samplemeta$Celltype) %>% unlist()
  return(as.numeric(res["p.value"]))
})

Celltype_kruskal_fdr = p.adjust(Celltype_kruskal, method = "fdr")

summarytab=cbind(sumstat, Geno.Treatment_kruskal, Geno.Treatment_kruskal_fdr , sumstatCelltype, Celltype_kruskal, Celltype_kruskal_fdr)

summarytab %>% display_tab()
Warning in instance$preRenderHook(instance): It seems your data is too big for client-side DataTables. You may consider server-side processing: https://rstudio.github.io/DT/server.htmlHierarchical clustering
to check where the variance in the data comes from
log2_cpm = log2(counts+1)

varsset=apply(log2_cpm, 1, var)

cpm.sel.trans = t(log2_cpm[order(varsset,decreasing = T)[1:1000],])

distance = dist(cpm.sel.trans)

sampleDistMatrix <- as.matrix(distance)

#colors for plotting heatmap
colors <- rev(colorRampPalette(brewer.pal(9, "Spectral"))(255))
colors=jetcolors(255)
colors=viridis(255)

cellcol = Dark8[1:nlevels(samplemeta$Celltype)]
names(cellcol) = levels(samplemeta$Celltype)

genotypecol = brewer.pal(4,"Accent")[c(1:nlevels(samplemeta$Genotype_corr))]
names(genotypecol) = levels(samplemeta$Genotype_corr)

strokecol = brewer.pal(5,"Set2")[1:nlevels(samplemeta$Treatment)+2]
names(strokecol) = levels(samplemeta$Treatment)

mousecol = brewer.pal(9,"Set1")[1:nlevels(samplemeta$Mouse_ID)]
names(mousecol) = levels(samplemeta$Mouse_ID)

braincol = brewer.pal(3,"Set2")[1:nlevels(samplemeta$Brain_region)]
names(braincol) = levels(samplemeta$Brain_region)

samplemeta$Age = as.factor(samplemeta$Age)
Agecol = colorRampPalette(c("dodgerblue",
                          "dodgerblue4"))(nlevels(samplemeta$Age))[1:nlevels(samplemeta$Age)]
names(Agecol) = as.character(sort(as.numeric(levels(samplemeta$Age))))

ann_colors = list(
  Genotype_corr = genotypecol,
  Mouse_ID = mousecol,
  Brain_region = braincol,
  Celltype=cellcol,
  Treatment=strokecol,
  Age=Agecol
)

labels = samplemeta[,c("Genotype_corr","Mouse_ID", "Age", "Brain_region", "Celltype", "Treatment")] %>%
  mutate_all(as.character) %>% as.data.frame()
labels$Age = as.numeric(labels$Age)
rownames(labels)=rownames(samplemeta)

pheatmap(sampleDistMatrix,
         clustering_distance_rows = distance,
         clustering_distance_cols = distance,
         clustering_method = "ward.D2",
         scale ="none",
         legend = F,
         show_rownames=F, show_colnames = F,
         border_color = NA,
         annotation_row = labels,
         annotation_col = labels,
         annotation_colors = ann_colors,
         col = colors,
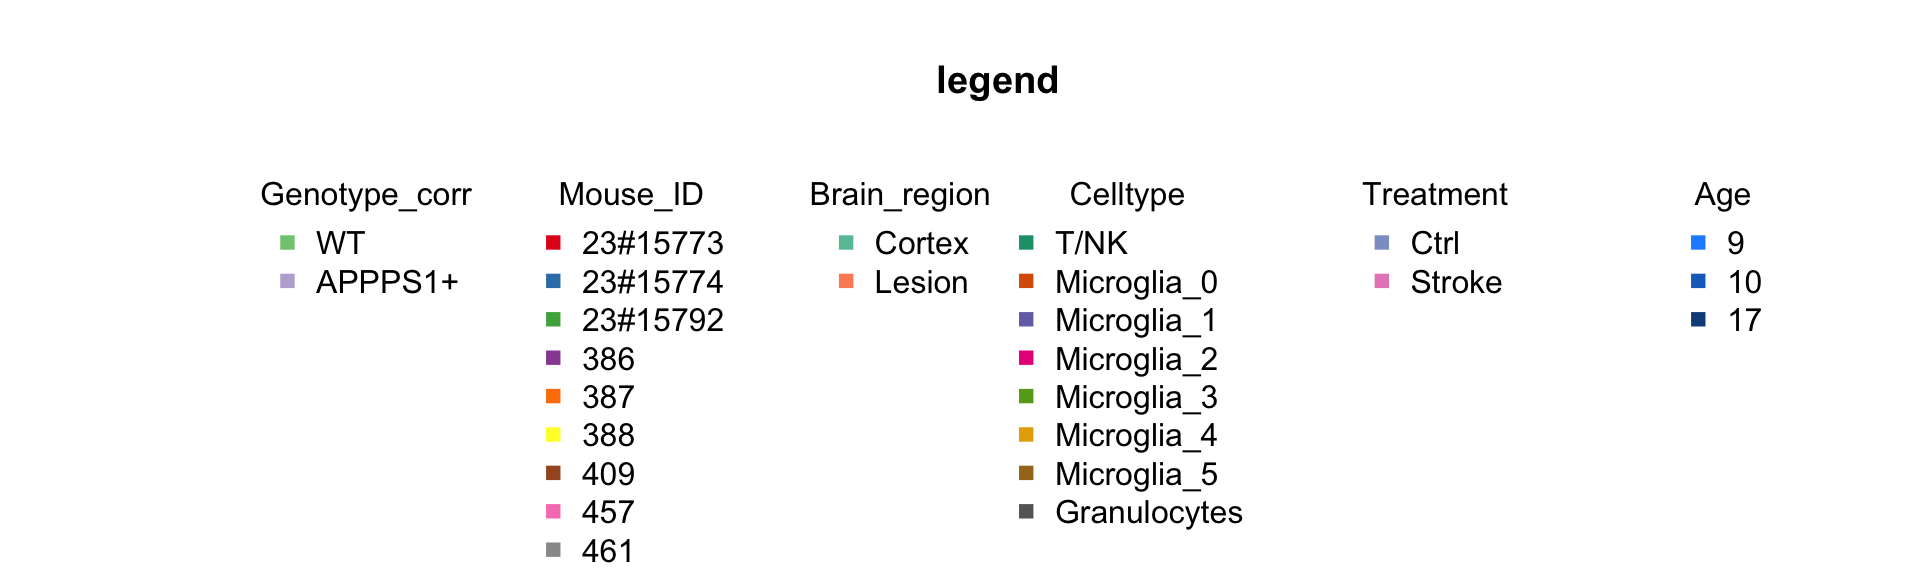
         main = "D62 top1000 Distances normalized log2 counts")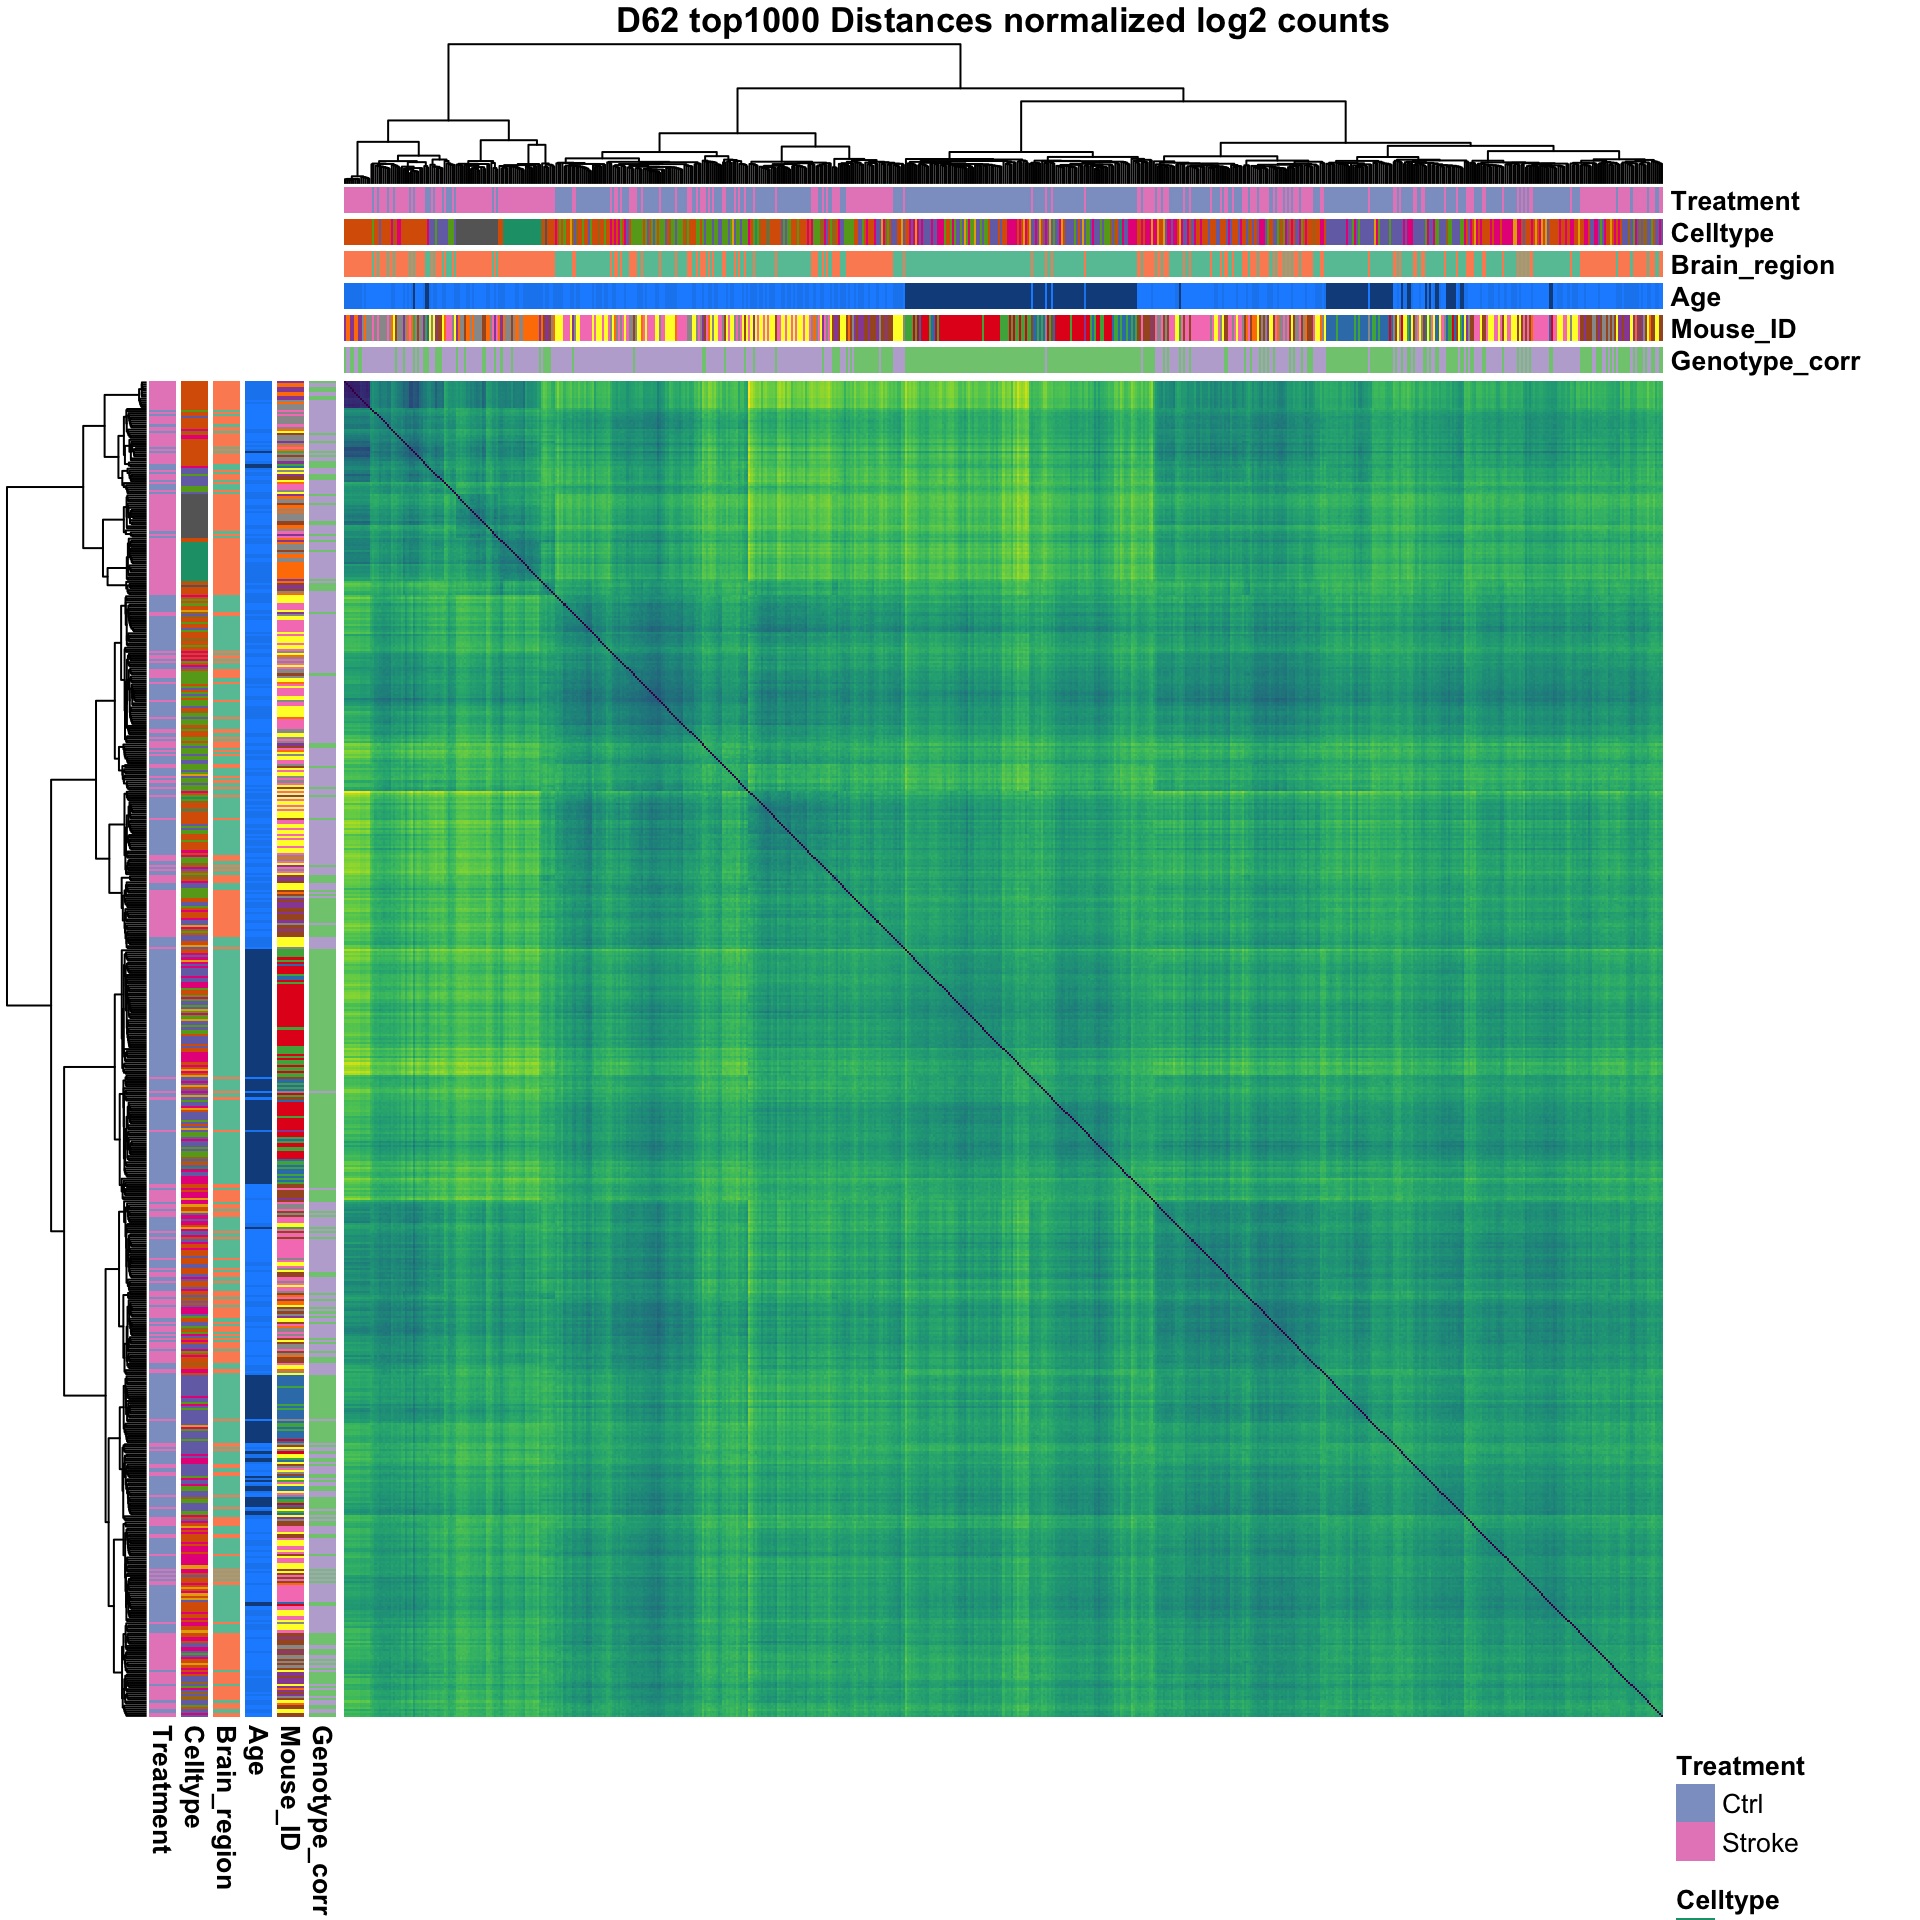
| Version | Author | Date |
|---|---|---|
| cfbfcf6 | achiocch | 2022-06-22 |
Genotype X Treatment Statistical modelling
the logFC should not be interpreted on its own without the specific post hoc tests (see app below to check the individual genes) In any case the value here would correspond to the APPPS1+ with Stroke against all others.
Heatmaps show standardized deviations from mean across all cells, trimmed to 2 standard deviations ( i.e. values above 2 SD are set to 2 SD). this allows to see more subtle changes better.
getres=function(Celltype="Specify",
                Hypothesis="~1+Sex+Genotype_corr*Treatment",
                Target="Genotype_corrAPPPS1+:TreatmentStroke",
                Randomeffect=NULL){

  res= comparison_rand(designform =Hypothesis,
                       randomeffect = Randomeffect,
                       Samples = samplemeta$Celltype==Celltype,
                       log_cpm = log2_cpm,
                       samplesdata = samplemeta,
                       target=Target)


  labels = samplemeta[samplemeta$Celltype==Celltype,c("Treatment","Age", "Genotype_corr","Mouse_ID", "Brain_region", "Celltype")] %>%
    mutate_all(as.character) %>% as.data.frame()
  labels$Age = as.numeric(labels$Age)

  labels=labels %>% arrange(Treatment,Genotype_corr)
  plotdata=log2_cpm[res$adj.P.Val<0.05,rownames(labels)]
  plotdata = apply(plotdata, 2, trimmed_scaled)


  pheatmap(plotdata,
           #clustering_method = "ward.D2",
           cluster_cols = F,
           cluster_rows  = T,
           scale ="row",
           show_rownames=F, show_colnames = F,
           legend=T,
           border_color = NA,
           #annotation_row = labels,
           annotation_col = labels,
           annotation_colors = ann_colors,
           col = colors,
           breaks = seq(-2,2, length.out=254),
           main = "D62 Distances normalized log2 counts")
  return(res)

}

generate_output=function(CT="Celltype", ...){
  respath=paste0(home, "/docs/LMER_",CT,".xlsx")

  analysis = getres(Celltype = CT)
  analysis_sig = analysis[analysis$adj.P.Val<0.05,]
  analysis_sig %>% display_tab()

  write.xlsx2(analysis_sig, file =respath , sheetName = "significant genes")

  ResGO = getGOresults(rownames(analysis_sig),
                       rownames(analysis),
                       "mmusculus")

  if(length(ResGO)>0){
    p=gostplot(ResGO)
  } else{
    ResGO=data.frame(result="no significant enrichment identified")
    p="no significant enrichment identified"
  }

  write.xlsx2(ResGO$result, file = respath, sheetName = "GO_enrichment", append=T)
  return(list(results=analysis,results_sig=analysis_sig, plot=p))
}
Microglia_0
res_output=generate_output("Microglia_0")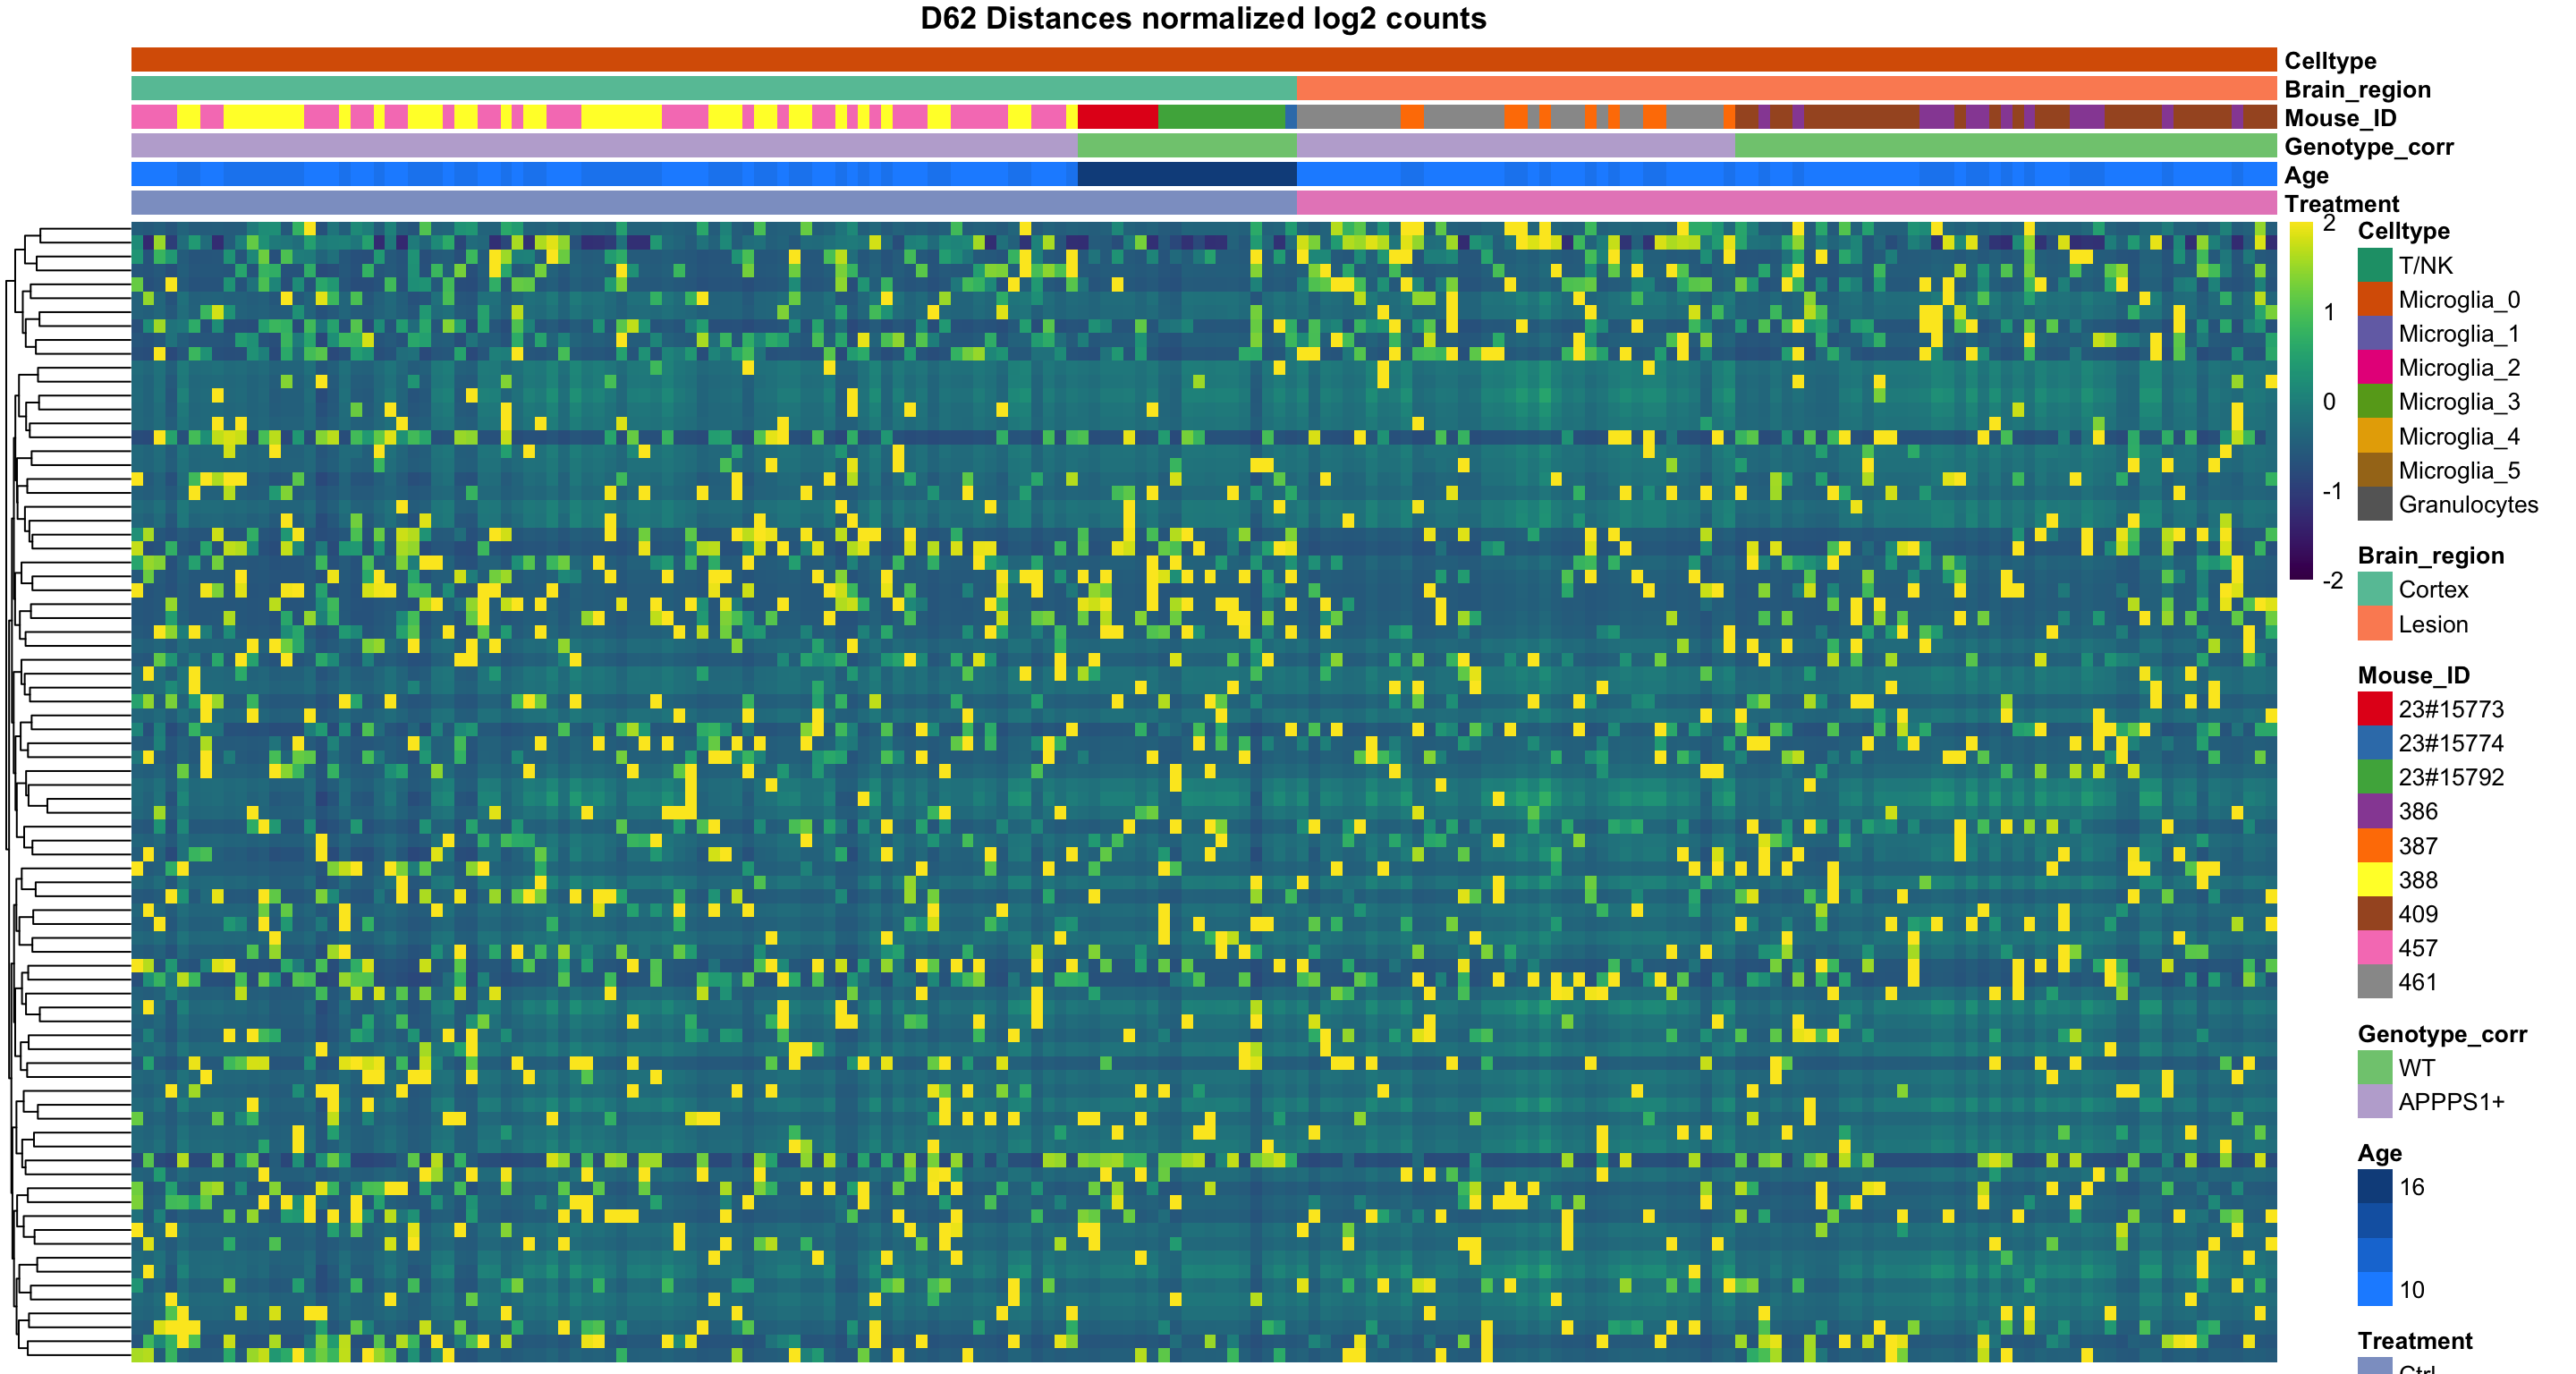
res_output[["results_sig"]] %>% display_tab()res_output[["plot"]]Data sources and their abbreviations are: Gene Ontology (GO or by branch GO:MF, GO:BP, GO:CC)KEGG (KEGG) TRANSFAC (TF) miRTarBase (MIRNA) CORUM (CORUM) Human phenotype ontology (HP) Human Protein Atlas (HPA)
get results table here
Microglia_1
res_output=generate_output(CT = "Microglia_1")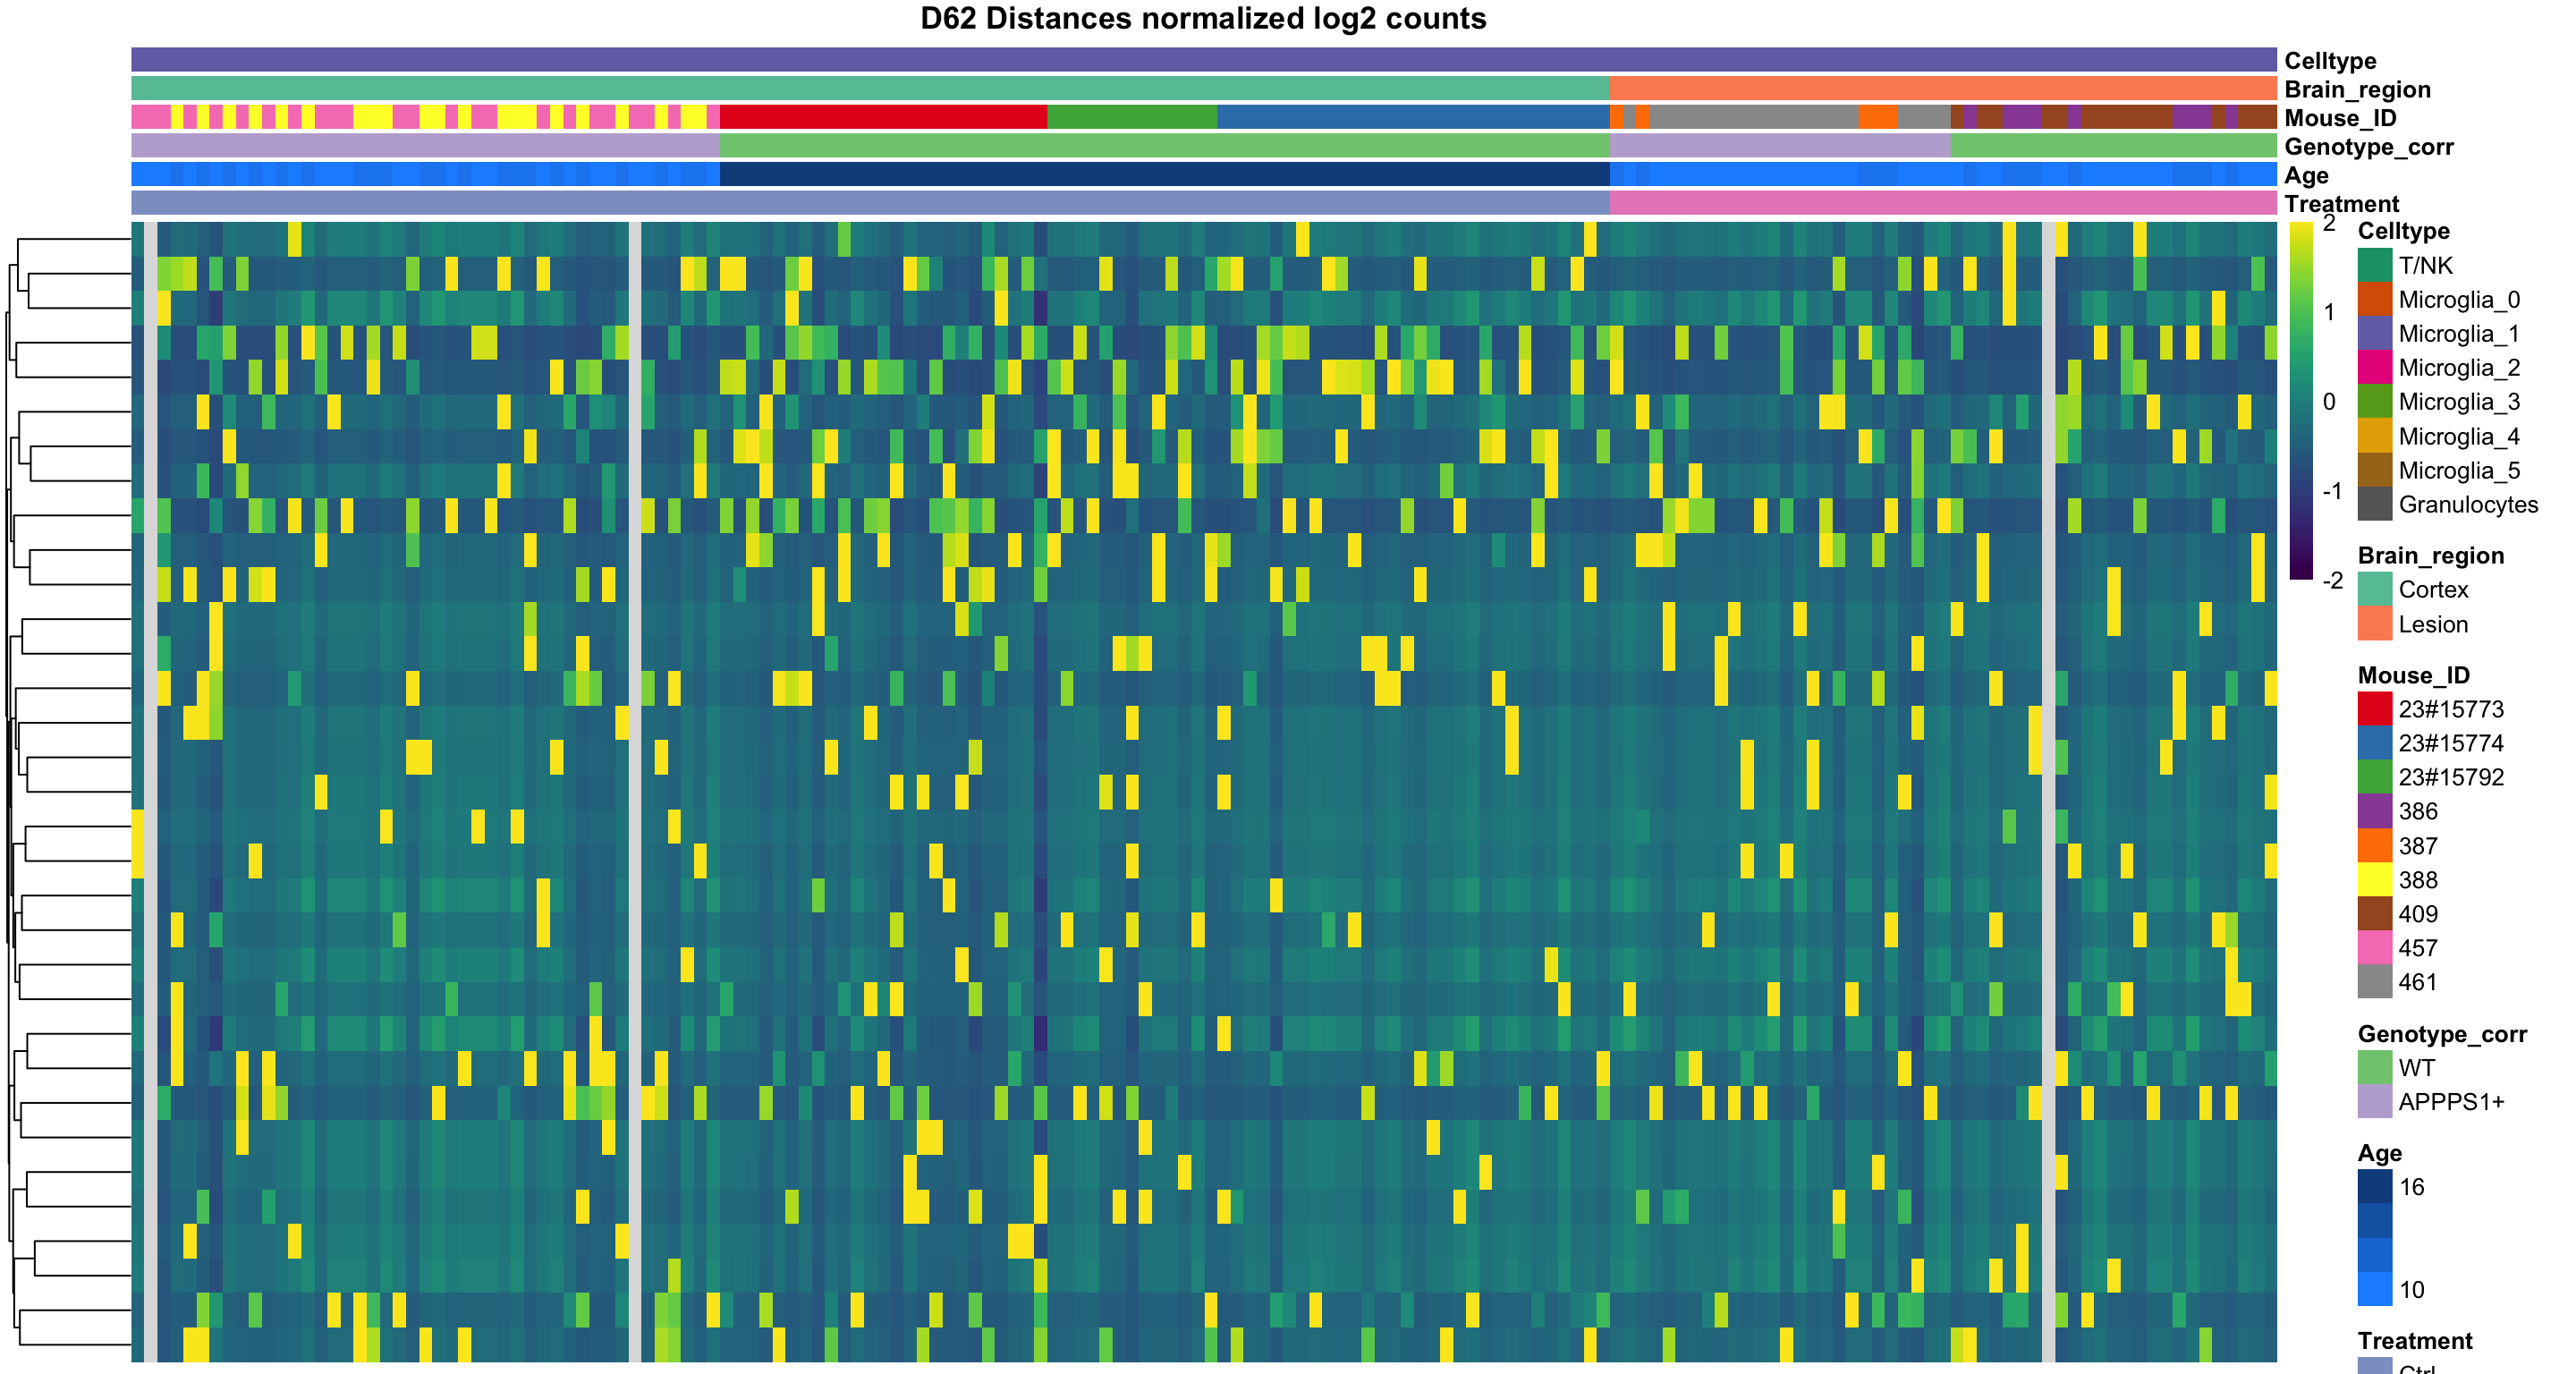
res_output[["results_sig"]] %>% display_tab()res_output[["plot"]]Data sources and their abbreviations are: Gene Ontology (GO or by branch GO:MF, GO:BP, GO:CC)KEGG (KEGG) TRANSFAC (TF) miRTarBase (MIRNA) CORUM (CORUM) Human phenotype ontology (HP) Human Protein Atlas (HPA)
get results table here
Microglia_2
res_output=generate_output("Microglia_2")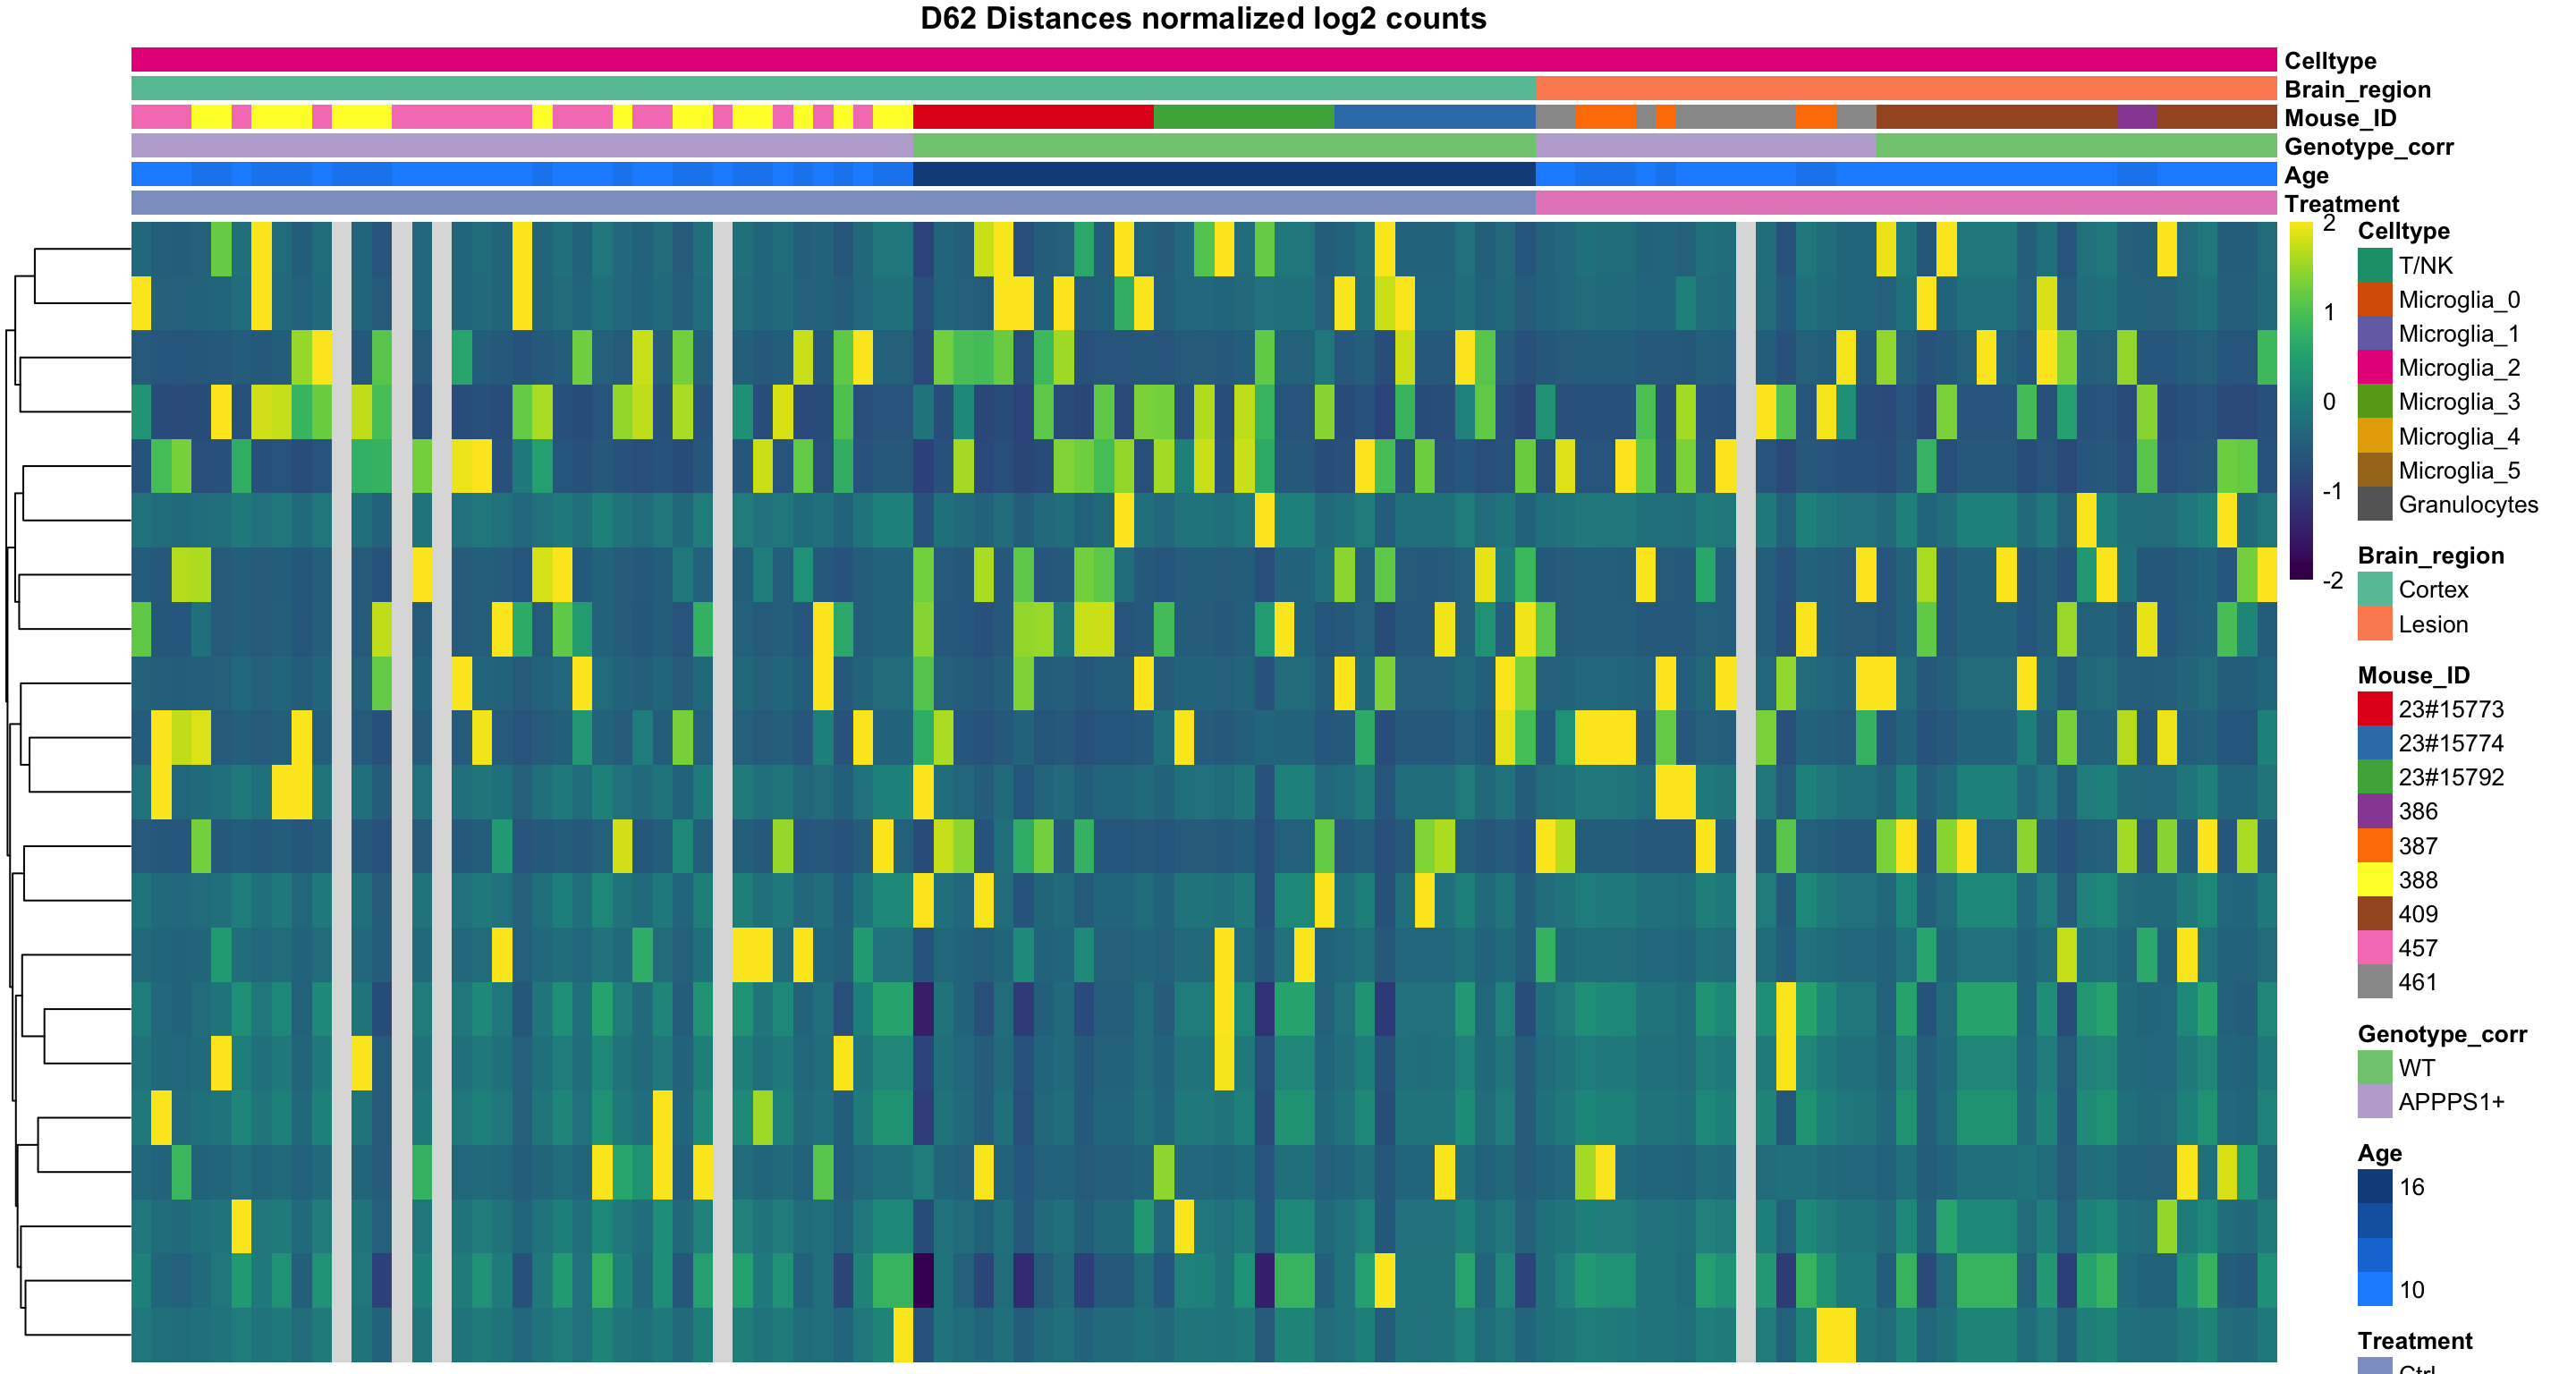
res_output[["results_sig"]] %>% display_tab()res_output[["plot"]]Data sources and their abbreviations are: Gene Ontology (GO or by branch GO:MF, GO:BP, GO:CC)KEGG (KEGG) TRANSFAC (TF) miRTarBase (MIRNA) CORUM (CORUM) Human phenotype ontology (HP) Human Protein Atlas (HPA)
get results table here
Microglia_3
res_output=generate_output("Microglia_3")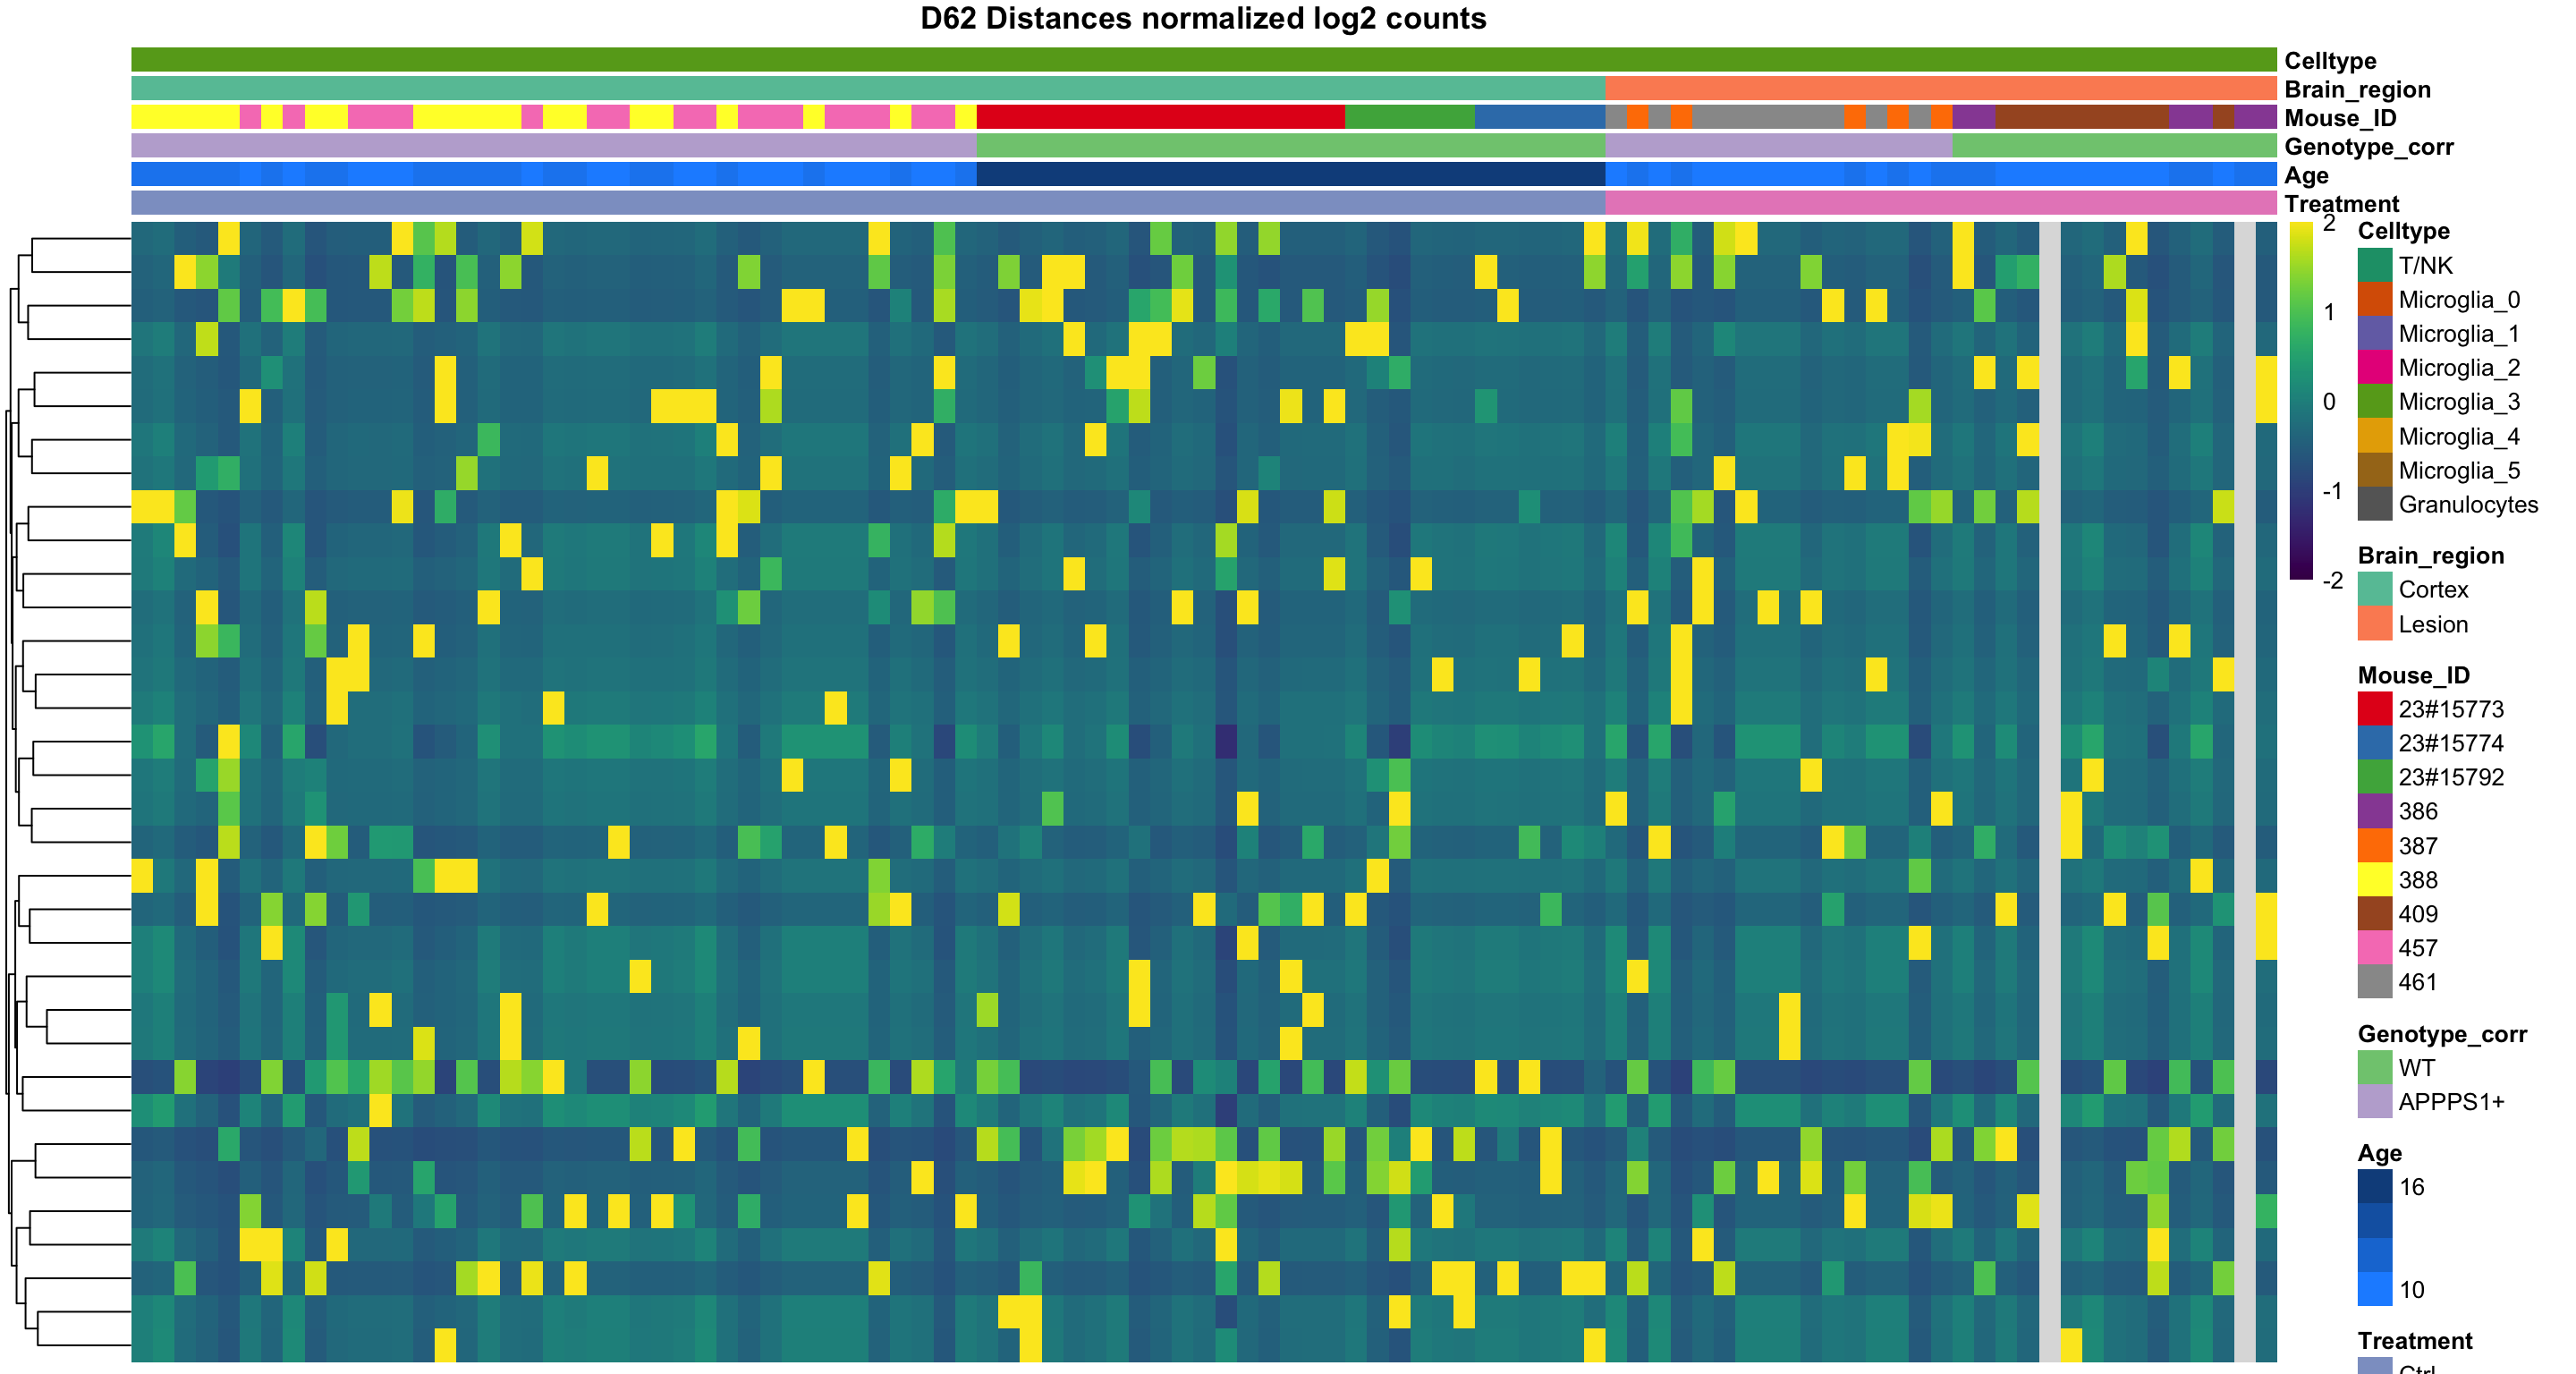
[1] "no significant GO terms identified"res_output[["results_sig"]] %>% display_tab()res_output[["plot"]][1] "no significant enrichment identified"Data sources and their abbreviations are: Gene Ontology (GO or by branch GO:MF, GO:BP, GO:CC)KEGG (KEGG) TRANSFAC (TF) miRTarBase (MIRNA) CORUM (CORUM) Human phenotype ontology (HP) Human Protein Atlas (HPA)
get results table here
Microglia_4
calculation not converging as Celltype not identified in all conditions however also rare in other conditions, no significant difference
idx=samplemeta$Celltype=="Microglia_4"
table(samplemeta$Treatment[idx], samplemeta$Genotype_corr[idx])
         WT APPPS1+
  Ctrl   11      10
  Stroke  4       1
table(samplemeta$Treatment[idx], samplemeta$Genotype_corr[idx]) %>% fisher.test()
    Fisher's Exact Test for Count Data

data:  .
p-value = 0.3562
alternative hypothesis: true odds ratio is not equal to 1
95 percent confidence interval:
 0.005090941 3.588141911
sample estimates:
odds ratio
 0.2877466
#res_output=generate_output("Microglia_4")
#res_output[["results_sig"]] %>% display_tab()
#res_output[["plot"]]get results table here
Microglia_5
res_output=generate_output("Microglia_5")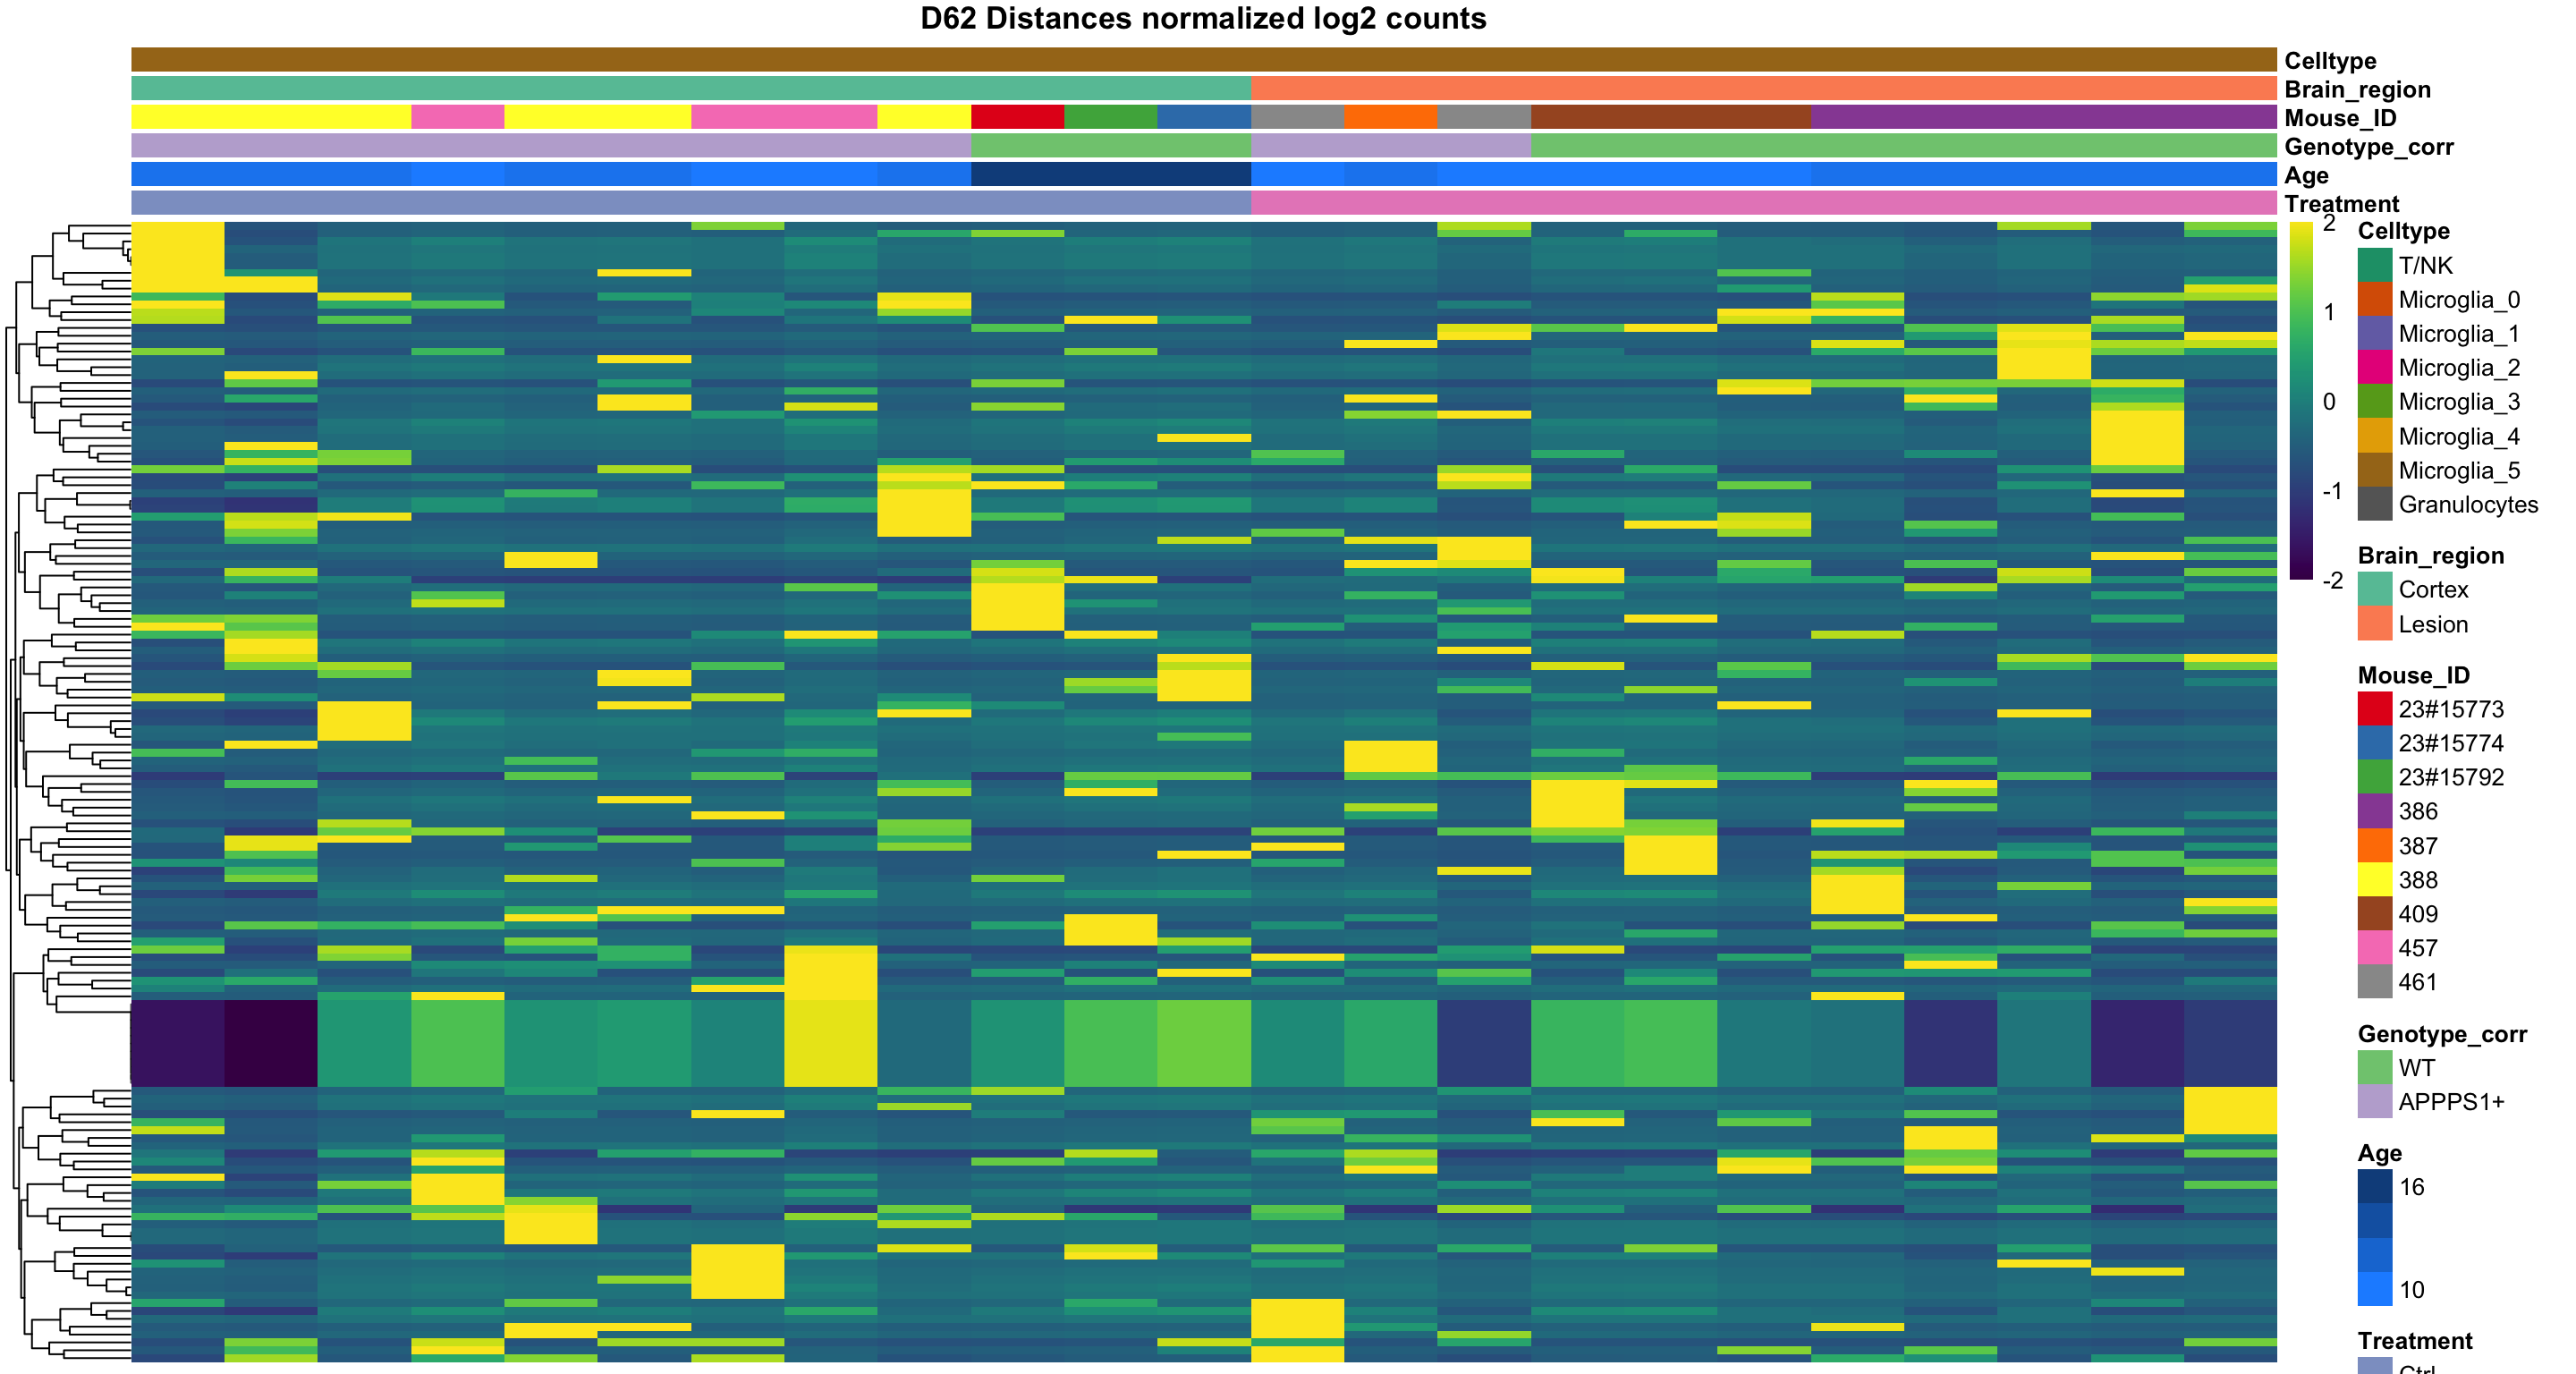
[1] "no significant GO terms identified"res_output[["results_sig"]] %>% display_tab()res_output[["plot"]][1] "no significant enrichment identified"Data sources and their abbreviations are: Gene Ontology (GO or by branch GO:MF, GO:BP, GO:CC)KEGG (KEGG) TRANSFAC (TF) miRTarBase (MIRNA) CORUM (CORUM) Human phenotype ontology (HP) Human Protein Atlas (HPA) get results table here
Granulozytes
calculation not converging as Celltype not identified in all conditions however also rare in other conditions, no significant difference
idx=samplemeta$Celltype=="Granulocytes"
table(samplemeta$Treatment[idx], samplemeta$Genotype_corr[idx])
         WT APPPS1+
  Ctrl    0       2
  Stroke  6      14
table(samplemeta$Treatment[idx], samplemeta$Genotype_corr[idx]) %>% fisher.test()
    Fisher's Exact Test for Count Data

data:  .
p-value = 1
alternative hypothesis: true odds ratio is not equal to 1
95 percent confidence interval:
  0.0000 14.7518
sample estimates:
odds ratio
         0
# res_output=generate_output("Granulocytes ")
# res_output[["results_sig"]] %>% display_tab()
# res_output[["plot"]]get results table here
T_NK
idx=samplemeta$Celltype=="T/NK"
table(samplemeta$Treatment[idx], samplemeta$Genotype_corr[idx])
         WT APPPS1+
  Ctrl    1       2
  Stroke  2      17
table(samplemeta$Treatment[idx], samplemeta$Genotype_corr[idx]) %>% fisher.test()
    Fisher's Exact Test for Count Data

data:  .
p-value = 0.3708
alternative hypothesis: true odds ratio is not equal to 1
95 percent confidence interval:
   0.0481749 117.2316789
sample estimates:
odds ratio
  3.869104
# res_output=generate_output("T/NK")
# res_output[["results_sig"]] %>% display_tab()
# res_output[["plot"]]get results table here
library(slingshot)Loading required package: princurveLoading required package: TrajectoryUtilsLoading required package: SingleCellExperimentlibrary(SingleCellExperiment)
sce=as.SingleCellExperiment(samples.integrated)
sce <- slingshot(sce, clusterLabels = 'Celltype', reducedDim = 'UMAP')
colors <- viridis(100)
plotcol <- colors[cut(sce$slingPseudotime_1, breaks=100)]
plot(reducedDims(sce)$UMAP, col = plotcol, pch=16, asp = 1)
lines(SlingshotDataSet(sce), lwd=2, col='black', type="l")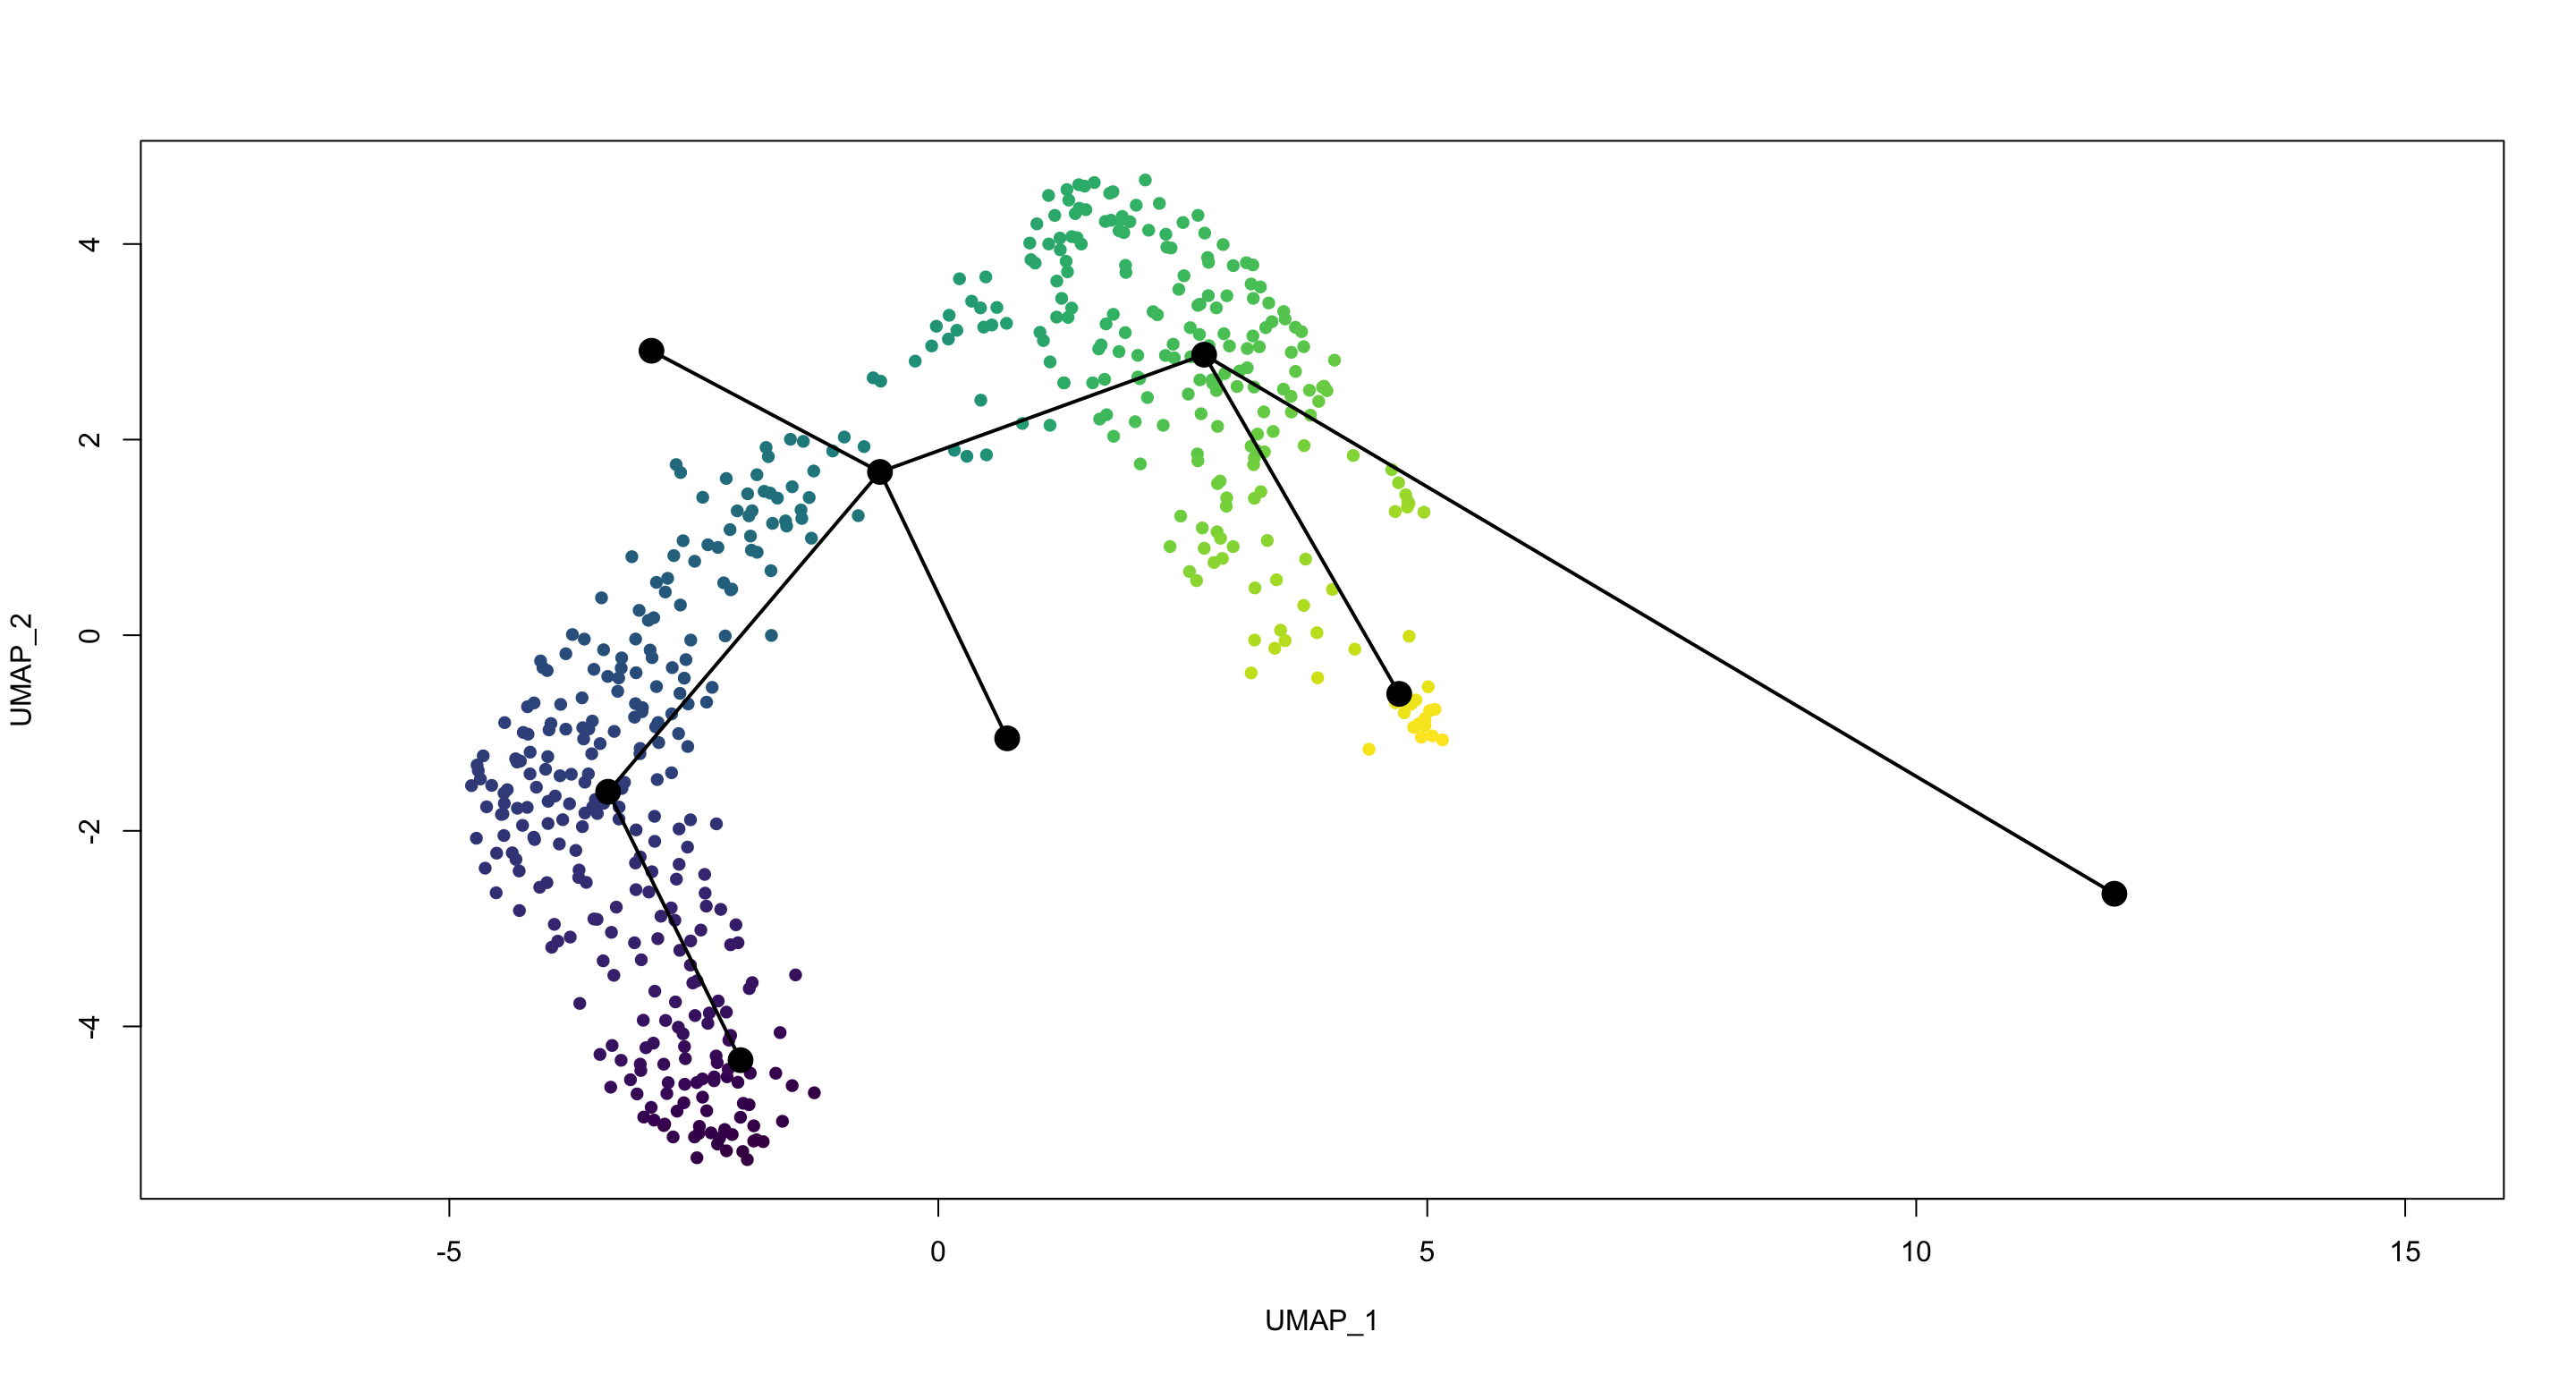
| Version | Author | Date |
|---|---|---|
| cfbfcf6 | achiocch | 2022-06-22 |
samplemeta$Pseudotime <- sce$slingPseudotime_1Gene expression plot
sessionInfo()R version 4.2.0 (2022-04-22)
Platform: x86_64-apple-darwin17.0 (64-bit)
Running under: macOS Big Sur/Monterey 10.16
Matrix products: default
BLAS: /Library/Frameworks/R.framework/Versions/4.2/Resources/lib/libRblas.0.dylib
LAPACK: /Library/Frameworks/R.framework/Versions/4.2/Resources/lib/libRlapack.dylib
locale:
[1] en_US.UTF-8/en_US.UTF-8/en_US.UTF-8/C/en_US.UTF-8/en_US.UTF-8
attached base packages:
[1] stats4 stats graphics grDevices utils datasets methods base
other attached packages:
[1] slingshot_2.4.0 TrajectoryUtils_1.4.0 SingleCellExperiment_1.18.0 princurve_2.1.6 gprofiler2_0.2.1 lm.beta_1.6-2 pheatmap_1.0.12 RColorBrewer_1.1-3 kableExtra_1.3.4 DT_0.23 viridis_0.6.2 viridisLite_0.4.0 xlsx_0.6.5 brms_2.17.0 Rcpp_1.0.8.3 compareGroups_4.5.1 data.table_1.14.2 SingleR_1.10.0 sp_1.5-0 SeuratObject_4.1.0 Seurat_4.1.1 forcats_0.5.1 stringr_1.4.0 dplyr_1.0.9 purrr_0.3.4 readr_2.1.2 tidyr_1.2.0 tibble_3.1.7 ggplot2_3.3.6 tidyverse_1.3.1 DESeq2_1.36.0 SummarizedExperiment_1.26.1 Biobase_2.56.0 MatrixGenerics_1.8.0 matrixStats_0.62.0 GenomicRanges_1.48.0 GenomeInfoDb_1.32.2 IRanges_2.30.0 S4Vectors_0.34.0 BiocGenerics_0.42.0 limma_3.52.2 workflowr_1.7.0
loaded via a namespace (and not attached):
[1] rsvd_1.0.5 ica_1.0-2 svglite_2.1.0 ps_1.7.1 lmtest_0.9-40 rprojroot_2.0.3 crayon_1.5.1 spatstat.core_2.4-4 MASS_7.3-57 nlme_3.1-158 backports_1.4.1 posterior_1.2.2 reprex_2.0.1 colourpicker_1.1.1 rlang_1.0.2 XVector_0.36.0 ROCR_1.0-11 readxl_1.4.0 irlba_2.3.5 callr_3.7.0 flextable_0.7.2 BiocParallel_1.30.3 bit64_4.0.5 glue_1.6.2 loo_2.5.1 sctransform_0.3.3 rstan_2.21.5 parallel_4.2.0 processx_3.6.1 spatstat.sparse_2.1-1 AnnotationDbi_1.58.0 spatstat.geom_2.4-0 haven_2.5.0 tidyselect_1.1.2 fitdistrplus_1.1-8 XML_3.99-0.10 zoo_1.8-10 packrat_0.8.0 distributional_0.3.0 chron_2.3-57 xtable_1.8-4 magrittr_2.0.3 evaluate_0.15 gdtools_0.2.4 cli_3.3.0 zlibbioc_1.42.0 rstudioapi_0.13 miniUI_0.1.1.1 whisker_0.4 bslib_0.3.1 rpart_4.1.16 shinystan_2.6.0 shiny_1.7.1 BiocSingular_1.12.0 xfun_0.31 askpass_1.1 inline_0.3.19 pkgbuild_1.3.1 cluster_2.1.3 bridgesampling_1.1-2 KEGGREST_1.36.2 Brobdingnag_1.2-7 ggrepel_0.9.1 threejs_0.3.3 listenv_0.8.0 xlsxjars_0.6.1 Biostrings_2.64.0 png_0.1-7 future_1.26.1 withr_2.5.0 bitops_1.0-7 plyr_1.8.7 cellranger_1.1.0 coda_0.19-4 pillar_1.7.0 RcppParallel_5.1.5 cachem_1.0.6 fs_1.5.2 DelayedMatrixStats_1.18.0 xts_0.12.1 vctrs_0.4.1 ellipsis_0.3.2 generics_0.1.2 dygraphs_1.1.1.6 tools_4.2.0 munsell_0.5.0 DelayedArray_0.22.0 fastmap_1.1.0 compiler_4.2.0 abind_1.4-5 httpuv_1.6.5 plotly_4.10.0 rgeos_0.5-9 rJava_1.0-6 GenomeInfoDbData_1.2.8 gridExtra_2.3 lattice_0.20-45 deldir_1.0-6 utf8_1.2.2 later_1.3.0 jsonlite_1.8.0 scales_1.2.0 ScaledMatrix_1.4.0 pbapply_1.5-0 sparseMatrixStats_1.8.0 genefilter_1.78.0 lazyeval_0.2.2 promises_1.2.0.1 goftest_1.2-3 spatstat.utils_2.3-1 reticulate_1.25 checkmate_2.1.0 rmarkdown_2.14 cowplot_1.1.1 webshot_0.5.3 Rtsne_0.16 uwot_0.1.11 igraph_1.3.2 survival_3.3-1 rsconnect_0.8.26 yaml_2.3.5 systemfonts_1.0.4 bayesplot_1.9.0 htmltools_0.5.2 rstantools_2.2.0 memoise_2.0.1 locfit_1.5-9.5 digest_0.6.29 assertthat_0.2.1 mime_0.12 RSQLite_2.2.14 future.apply_1.9.0 blob_1.2.3 shinythemes_1.2.0 splines_4.2.0 RCurl_1.98-1.7 broom_0.8.0 hms_1.1.1 modelr_0.1.8 colorspace_2.0-3 base64enc_0.1-3 BiocManager_1.30.18 nnet_7.3-17 sass_0.4.1 RANN_2.6.1 mvtnorm_1.1-3 fansi_1.0.3 tzdb_0.3.0 truncnorm_1.0-8 parallelly_1.32.0 R6_2.5.1 grid_4.2.0 ggridges_0.5.3 lifecycle_1.0.1 StanHeaders_2.21.0-7 zip_2.2.0 writexl_1.4.0 curl_4.3.2 leiden_0.4.2 jquerylib_0.1.4 Matrix_1.4-1 RcppAnnoy_0.0.19 htmlwidgets_1.5.4 officer_0.4.3 beachmat_2.12.0 polyclip_1.10-0 markdown_1.1 crosstalk_1.2.0 rvest_1.0.2 mgcv_1.8-40 globals_0.15.0 openssl_2.0.2 patchwork_1.1.1 spatstat.random_2.2-0 tensorA_0.36.2 progressr_0.10.1 codetools_0.2-18 lubridate_1.8.0 gtools_3.9.2.2 getPass_0.2-2 prettyunits_1.1.1 dbplyr_2.2.0 gtable_0.3.0 DBI_1.1.3 git2r_0.30.1 tensor_1.5 httr_1.4.3 highr_0.9 KernSmooth_2.23-20 stringi_1.7.6 reshape2_1.4.4 farver_2.1.0 uuid_1.1-0 annotate_1.74.0 mice_3.14.0 xml2_1.3.3 shinyjs_2.1.0 BiocNeighbors_1.14.0 geneplotter_1.74.0 scattermore_0.8 bit_4.0.4 spatstat.data_2.2-0 pkgconfig_2.0.3 HardyWeinberg_1.7.5 Rsolnp_1.16 knitr_1.39