Figure S4: Healthy non-thymocyte GP mean-loading heatmaps
Ziang Zhang
Last updated: 2026-07-28
Checks: 7 0
Knit directory:
immgenT-GP-analysis/analysis/
This reproducible R Markdown analysis was created with workflowr (version 1.7.2). The Checks tab describes the reproducibility checks that were applied when the results were created. The Past versions tab lists the development history.
Great! Since the R Markdown file has been committed to the Git repository, you know the exact version of the code that produced these results.
Great job! The global environment was empty. Objects defined in the global environment can affect the analysis in your R Markdown file in unknown ways. For reproduciblity it’s best to always run the code in an empty environment.
The command set.seed(1) was run prior to running the
code in the R Markdown file. Setting a seed ensures that any results
that rely on randomness, e.g. subsampling or permutations, are
reproducible.
Great job! Recording the operating system, R version, and package versions is critical for reproducibility.
Nice! There were no cached chunks for this analysis, so you can be confident that you successfully produced the results during this run.
Great job! Using relative paths to the files within your workflowr project makes it easier to run your code on other machines.
Great! You are using Git for version control. Tracking code development and connecting the code version to the results is critical for reproducibility.
The results in this page were generated with repository version d538aa2. See the Past versions tab to see a history of the changes made to the R Markdown and HTML files.
Note that you need to be careful to ensure that all relevant files for
the analysis have been committed to Git prior to generating the results
(you can use wflow_publish or
wflow_git_commit). workflowr only checks the R Markdown
file, but you know if there are other scripts or data files that it
depends on. Below is the status of the Git repository when the results
were generated:
Ignored files:
    Ignored:    .DS_Store
    Ignored:    .claude/
    Ignored:    analysis/.DS_Store
    Ignored:    analysis/.Rhistory
    Ignored:    analysis/assets/.DS_Store
    Ignored:    captions/
    Ignored:    code/.DS_Store
    Ignored:    code/other/topic_flashier_20250212.R
    Ignored:    code/other/topic_wrapper_20250215_alldata_backfit.sh
    Ignored:    data
    Ignored:    experiments/
    Ignored:    figures/.DS_Store
    Ignored:    figures/Previous/.DS_Store
    Ignored:    figures/Previous/bits/.DS_Store
    Ignored:    figures/Previous/bits/Figure 1/.DS_Store
    Ignored:    figures/Previous/bits/Figure 2/.DS_Store
    Ignored:    figures/Previous/bits/Figure 3/.DS_Store
    Ignored:    figures/Previous/bits/Figure 4/.DS_Store
    Ignored:    figures/Previous/bits/Figure 6/.DS_Store
    Ignored:    figures/Previous/bits/Figure 7/.DS_Store
    Ignored:    figures/Previous/bits/Figure S1/.DS_Store
    Ignored:    figures/Previous/bits/Figure S2/.DS_Store
    Ignored:    figures/Previous/bits/Figure S3/.DS_Store
    Ignored:    figures/Previous/bits/Figure S6/.DS_Store
    Ignored:    figures/Previous/bits/Figure S7/.DS_Store
    Ignored:    figures/final-selected/.DS_Store
    Ignored:    figures/final-selected/Figure 1/.DS_Store
    Ignored:    figures/final-selected/Figure 2/.DS_Store
    Ignored:    figures/final-selected/Figure S4/.DS_Store
    Ignored:    log/
    Ignored:    output/Figure2/
    Ignored:    output/Figure7b/7b_cell_metadata.csv.gz
    Ignored:    plan/
    Ignored:    reorder/
    Ignored:    tables/
    Ignored:    tmp/
Note that any generated files, e.g. HTML, png, CSS, etc., are not included in this status report because it is ok for generated content to have uncommitted changes.
These are the previous versions of the repository in which changes were
made to the R Markdown (analysis/FigureS4.Rmd) and HTML
(docs/FigureS4.html) files. If you’ve configured a remote
Git repository (see ?wflow_git_remote), click on the
hyperlinks in the table below to view the files as they were in that
past version.
| File | Version | Author | Date | Message |
|---|---|---|---|---|
| html | d538aa2 | Ziang Zhang | 2026-07-28 | Build site: reordered Figures 6 / S6 / S3 and the new Figure 7b page |
| html | 029b0ae | Ziang Zhang | 2026-07-28 | Build site. |
| Rmd | 0f5b5da | Ziang Zhang | 2026-07-28 | Align all figure captions with captions_20260728_final.docx |
| html | 3fc3789 | Ziang Zhang | 2026-07-27 | Republish all 24 pages |
| html | 1390a03 | Ziang Zhang | 2026-07-27 | Republish all 24 pages |
| html | adaef21 | Ziang Zhang | 2026-07-27 | Build site: panel fixes and PDF-derived assets |
| html | 5b19858 | Ziang Zhang | 2026-07-27 | Build site. |
| Rmd | 91ee059 | Ziang Zhang | 2026-07-26 | Select each panel’s code block by name, not by line number |
| html | 91ee059 | Ziang Zhang | 2026-07-26 | Select each panel’s code block by name, not by line number |
| Rmd | 3c052d6 | Ziang Zhang | 2026-07-15 | Finalize full-centered Figure S4 |
| html | 3c052d6 | Ziang Zhang | 2026-07-15 | Finalize full-centered Figure S4 |
| Rmd | 8938a27 | Ziang Zhang | 2026-07-14 | Update Figure S4 centered heatmaps |
| html | 8938a27 | Ziang Zhang | 2026-07-14 | Update Figure S4 centered heatmaps |
| Rmd | c344aaa | Ziang Zhang | 2026-07-13 | Add Figure S4 mean-loading heatmaps |
| html | c344aaa | Ziang Zhang | 2026-07-13 | Add Figure S4 mean-loading heatmaps |
Published as Extended Data Figure 4.
Figure S4 is produced by script/FigureS4.R.
Both panels show the final full row-centered matrices, with all 200 GPs
and all observed groups. The analysis uses healthy non-thymocyte cells
(condition_broad == "healthy" and
annotation_level1 != "thymocyte"). For each GP, its mean
loading across groups is subtracted from every group mean. The shared
centered color scale is fixed at -0.2 to 0.2; values outside this range
are saturated at the endpoint colors.
Setup, centering, and ordering
# Figure S4. Full row-centered healthy non-thymocyte GP mean-loading heatmaps.
#
# Panel S4a: tissue (organ_simplified), all 200 GPs and all tissues.
# Panel S4b: cluster (annotation_level2), all 200 GPs and all clusters.
#
# The shared centered color scale is fixed at [-0.2, 0.2]. Values outside
# this range saturate at the endpoint colors. Level2 columns follow Figure 1's
# level1 order, with level2 labels alphabetized within each level1 block.

suppressPackageStartupMessages({
  library(ComplexHeatmap)
  library(circlize)
  library(grid)
  library(ZemmourLib)
})

if (!file.exists("code/R/setup_data.R")) {
  stop("Run this script from the immgenT-GP-analysis repository root.")
}

source("code/R/setup_data.R")

figure_path <- "figures/final-selected/Figure S4"
dir.create(figure_path, recursive = TRUE, showWarnings = FALSE)

mean_loading_by_group <- function(L_mat, labels) {
  if (length(labels) != nrow(L_mat) || anyNA(labels) || any(labels == "")) {
    stop("Group labels must be present for every retained cell.")
  }

  labels <- droplevels(factor(as.character(labels)))
  group_sums <- rowsum(L_mat, group = labels, reorder = TRUE)
  group_counts <- as.integer(table(labels)[rownames(group_sums)])

  list(
    matrix = t(sweep(group_sums, 1L, group_counts, "/")),
    counts = data.frame(group = rownames(group_sums), n_cells = group_counts)
  )
}

center_by_gp_mean <- function(mean_matrix) {
  sweep(mean_matrix, 1L, rowMeans(mean_matrix), "-")
}

dominant_group_order <- function(raw_mean_matrix, fixed_column_order = NULL) {
  gp_number <- suppressWarnings(as.integer(sub("^GP", "", rownames(raw_mean_matrix))))
  if (ncol(raw_mean_matrix) < 2L || anyNA(gp_number)) {
    stop("Dominant-group ordering requires at least two groups and GP<number> row names.")
  }

  dominant_index <- max.col(raw_mean_matrix, ties.method = "first")
  dominant_mean <- raw_mean_matrix[cbind(seq_len(nrow(raw_mean_matrix)), dominant_index)]
  second_mean <- apply(raw_mean_matrix, 1L, function(values) sort(values, decreasing = TRUE)[2L])
  dominance_gap <- dominant_mean - second_mean

  if (is.null(fixed_column_order)) {
    dominant_gp_count <- tabulate(dominant_index, nbins = ncol(raw_mean_matrix))
    column_order <- order(-dominant_gp_count, -colMeans(raw_mean_matrix), colnames(raw_mean_matrix))
  } else {
    if (
      length(fixed_column_order) != ncol(raw_mean_matrix) ||
      !identical(sort(fixed_column_order), seq_len(ncol(raw_mean_matrix)))
    ) {
      stop("The fixed column order must be a complete permutation.")
    }
    column_order <- fixed_column_order
  }

  dominant_group_position <- match(dominant_index, column_order)
  row_order <- order(dominant_group_position, -dominance_gap, -dominant_mean, gp_number)

  if (any(diff(dominant_group_position[row_order]) < 0L)) {
    stop("Dominant-group blocks are not monotone after ordering.")
  }

  list(row_order = row_order, column_order = column_order)
}

level2_to_level1_map <- function(meta, groups, level1_order) {
  mapping <- unique(data.frame(
    group = as.character(meta$annotation_level2),
    level1 = as.character(meta$annotation_level1),
    stringsAsFactors = FALSE
  ))
  if (anyDuplicated(mapping$group)) {
    stop("Each annotation_level2 label must map to exactly one annotation_level1 label.")
  }

  group_level1 <- mapping$level1[match(groups, mapping$group)]
  names(group_level1) <- groups
  if (anyNA(group_level1) || any(!group_level1 %in% level1_order)) {
    stop("Every displayed level2 group must map to the Figure 1 level1 order.")
  }
  group_level1
}

level2_column_order <- function(groups, group_level1, level1_order) {
  order(match(group_level1[groups], level1_order), groups)
}

palette_for_groups <- function(groups, palette, label) {
  missing <- setdiff(groups, names(palette))
  if (length(missing) > 0L) {
    stop("The canonical ", label, " palette lacks: ", paste(missing, collapse = ", "))
  }
  palette[groups]
}

render_centered_heatmap <- function(
    matrix,
    group_palette,
    group_label,
    filename,
    row_order,
    column_order,
    centered_color_limit,
    order_description,
    group_level1 = NULL,
    level1_palette = NULL
) {
  if (
    length(row_order) != nrow(matrix) || length(column_order) != ncol(matrix) ||
    !identical(sort(row_order), seq_len(nrow(matrix))) ||
    !identical(sort(column_order), seq_len(ncol(matrix)))
  ) {
    stop("Fixed row and column orders must be complete permutations.")
  }

  color_fun <- circlize::colorRamp2(
    c(-centered_color_limit, 0, centered_color_limit),
    c("#2166AC", "#FFFFFF", "#B2182B")
  )
  legend_at <- c(-centered_color_limit, 0, centered_color_limit)

  heatmap_width_mm <- max(180, ncol(matrix) * 4.2)
  heatmap_height_mm <- max(160, nrow(matrix) * 3.5)
  pdf_width_in <- (heatmap_width_mm + 130) / 25.4
  pdf_height_in <- (heatmap_height_mm + 90) / 25.4
  cell_width_mm <- heatmap_width_mm / ncol(matrix)
  cell_height_mm <- heatmap_height_mm / nrow(matrix)
  row_label_fontsize <- min(14, max(9, floor(cell_height_mm * 2.8)))
  column_label_fontsize <- min(14, max(9, floor(cell_width_mm * 2.8)))

  if (is.null(group_level1)) {
    column_annotation <- ComplexHeatmap::HeatmapAnnotation(
      group = factor(colnames(matrix), levels = colnames(matrix)),
      col = list(group = group_palette),
      show_legend = FALSE,
      annotation_name_side = "left",
      annotation_name_gp = grid::gpar(fontsize = 10, fontface = "bold"),
      annotation_height = grid::unit(4, "mm")
    )
  } else {
    group_level1 <- group_level1[colnames(matrix)]
    if (anyNA(group_level1) || is.null(level1_palette)) {
      stop("Level2 heatmaps require complete level1 annotations and a palette.")
    }
    column_annotation <- ComplexHeatmap::HeatmapAnnotation(
      level1 = factor(group_level1, levels = names(level1_palette)),
      group = factor(colnames(matrix), levels = colnames(matrix)),
      col = list(level1 = level1_palette, group = group_palette),
      show_legend = FALSE,
      annotation_name_side = "left",
      annotation_name_gp = grid::gpar(fontsize = 10, fontface = "bold"),
      annotation_height = grid::unit(c(4, 4), "mm")
    )
  }

  heatmap <- ComplexHeatmap::Heatmap(
    matrix,
    name = "Row-centered mean loading",
    col = color_fun,
    cluster_rows = FALSE,
    cluster_columns = FALSE,
    row_order = row_order,
    column_order = column_order,
    top_annotation = column_annotation,
    column_title = paste0(
      "Row-centered GP mean loading: ", group_label, "\n", order_description
    ),
    column_title_gp = grid::gpar(fontsize = 16, fontface = "bold"),
    row_title = "GP",
    row_title_gp = grid::gpar(fontsize = 12),
    row_names_gp = grid::gpar(fontsize = row_label_fontsize),
    column_names_gp = grid::gpar(fontsize = column_label_fontsize),
    column_names_rot = 90,
    heatmap_legend_param = list(
      title = "Row-centered mean loading",
      at = legend_at,
      labels = format(legend_at, trim = TRUE, scientific = FALSE),
      title_gp = grid::gpar(fontsize = 11, fontface = "bold"),
      labels_gp = grid::gpar(fontsize = 10)
    ),
    width = grid::unit(heatmap_width_mm, "mm"),
    height = grid::unit(heatmap_height_mm, "mm"),
    use_raster = TRUE,
    raster_quality = 2
  )

  grDevices::pdf(filename, width = pdf_width_in, height = pdf_height_in)
  ComplexHeatmap::draw(
    heatmap,
    heatmap_legend_side = "right",
    padding = grid::unit(c(8, 8, 8, 8), "mm")
  )
  grDevices::dev.off()
}

gp_data <- load_gp_data()
meta <- gp_data$seurat_meta_filtered
healthy_nonthymus <- meta$condition_broad == "healthy" & meta$annotation_level1 != "thymocyte"

if (anyNA(healthy_nonthymus)) {
  stop("Healthy non-thymocyte selection contains missing values.")
}

L_reference <- gp_data$L_pm_filtered[healthy_nonthymus, , drop = FALSE]
meta_reference <- meta[healthy_nonthymus, , drop = FALSE]
if (ncol(L_reference) != 200L || nrow(L_reference) != nrow(meta_reference) || anyNA(L_reference)) {
  stop("The healthy non-thymocyte loading matrix has unexpected dimensions or missing values.")
}

centered_color_limit <- 0.2
level1_order <- c("CD8", "CD4", "Treg", "gdT", "CD8aa", "Tz", "DN", "DP")
organ_result <- mean_loading_by_group(L_reference, meta_reference$organ_simplified)
level2_result <- mean_loading_by_group(L_reference, meta_reference$annotation_level2)
organ_raw <- organ_result$matrix
level2_raw <- level2_result$matrix
organ_centered <- center_by_gp_mean(organ_raw)
level2_centered <- center_by_gp_mean(level2_raw)

level2_group_level1 <- level2_to_level1_map(
  meta_reference, colnames(level2_raw), level1_order
)
organ_order <- dominant_group_order(organ_raw)
level2_order <- dominant_group_order(
  level2_raw,
  level2_column_order(colnames(level2_raw), level2_group_level1, level1_order)
)

stopifnot(
  nrow(organ_centered) == 200L,
  nrow(level2_centered) == 200L,
  ncol(organ_centered) == 18L,
  ncol(level2_centered) == 107L,
  max(abs(rowMeans(organ_centered))) < 1e-12,
  max(abs(rowMeans(level2_centered))) < 1e-12
)

organ_palette <- palette_for_groups(
  colnames(organ_centered),
  ZemmourLib::immgent_colors$organ_simplified,
  "organ_simplified"
)
level2_palette <- palette_for_groups(
  colnames(level2_centered),
  ZemmourLib::immgent_colors$level2,
  "annotation_level2"
)
level1_palette <- ZemmourLib::immgent_colors$level1[level1_order]
(a) Tissue mean loading
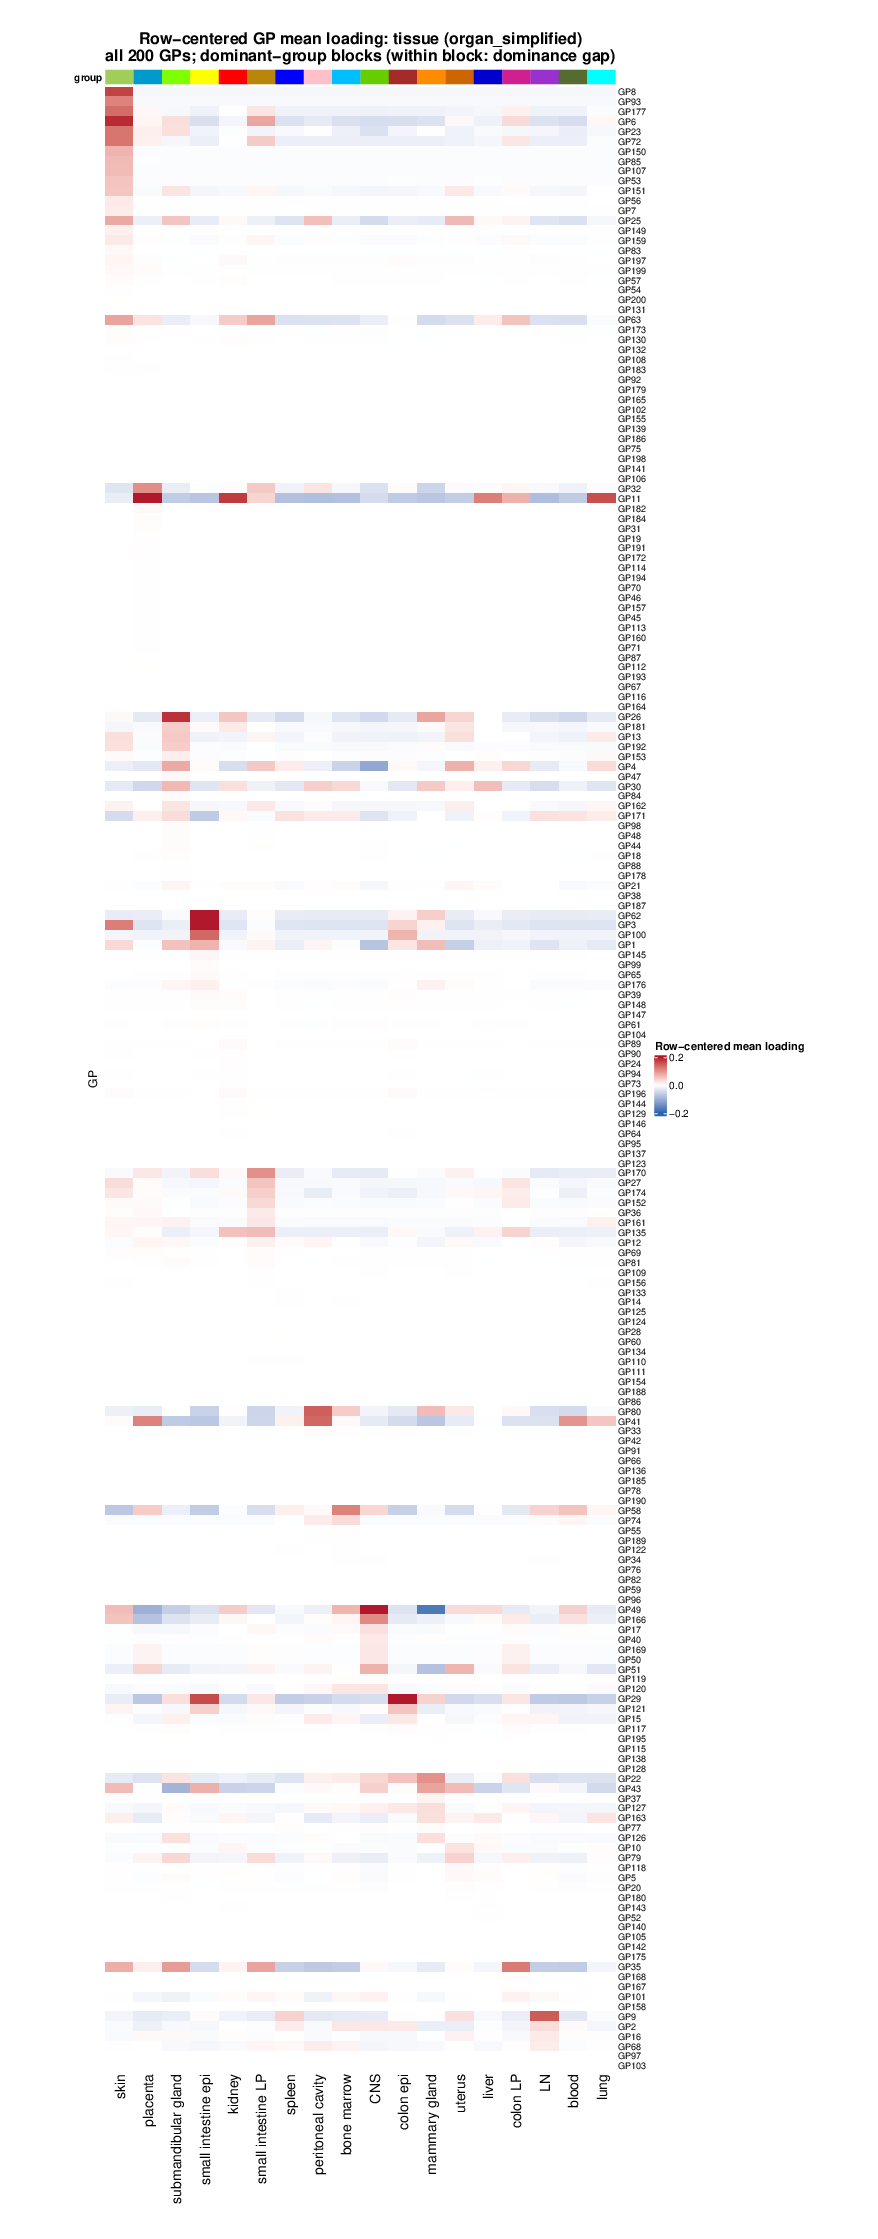
Fig. S4a. Row-centered mean GP activity across the
18 organ_simplified tissues for all 200 GPs. Each GP is
assigned to the tissue with its largest raw mean activity; tissues are
ordered by their number of assigned GPs, and GPs are grouped by assigned
tissue – within each block, ordered by decreasing dominance gap. The
centered color scale is fixed at -0.2 to 0.2.
(b) Level2 mean loading
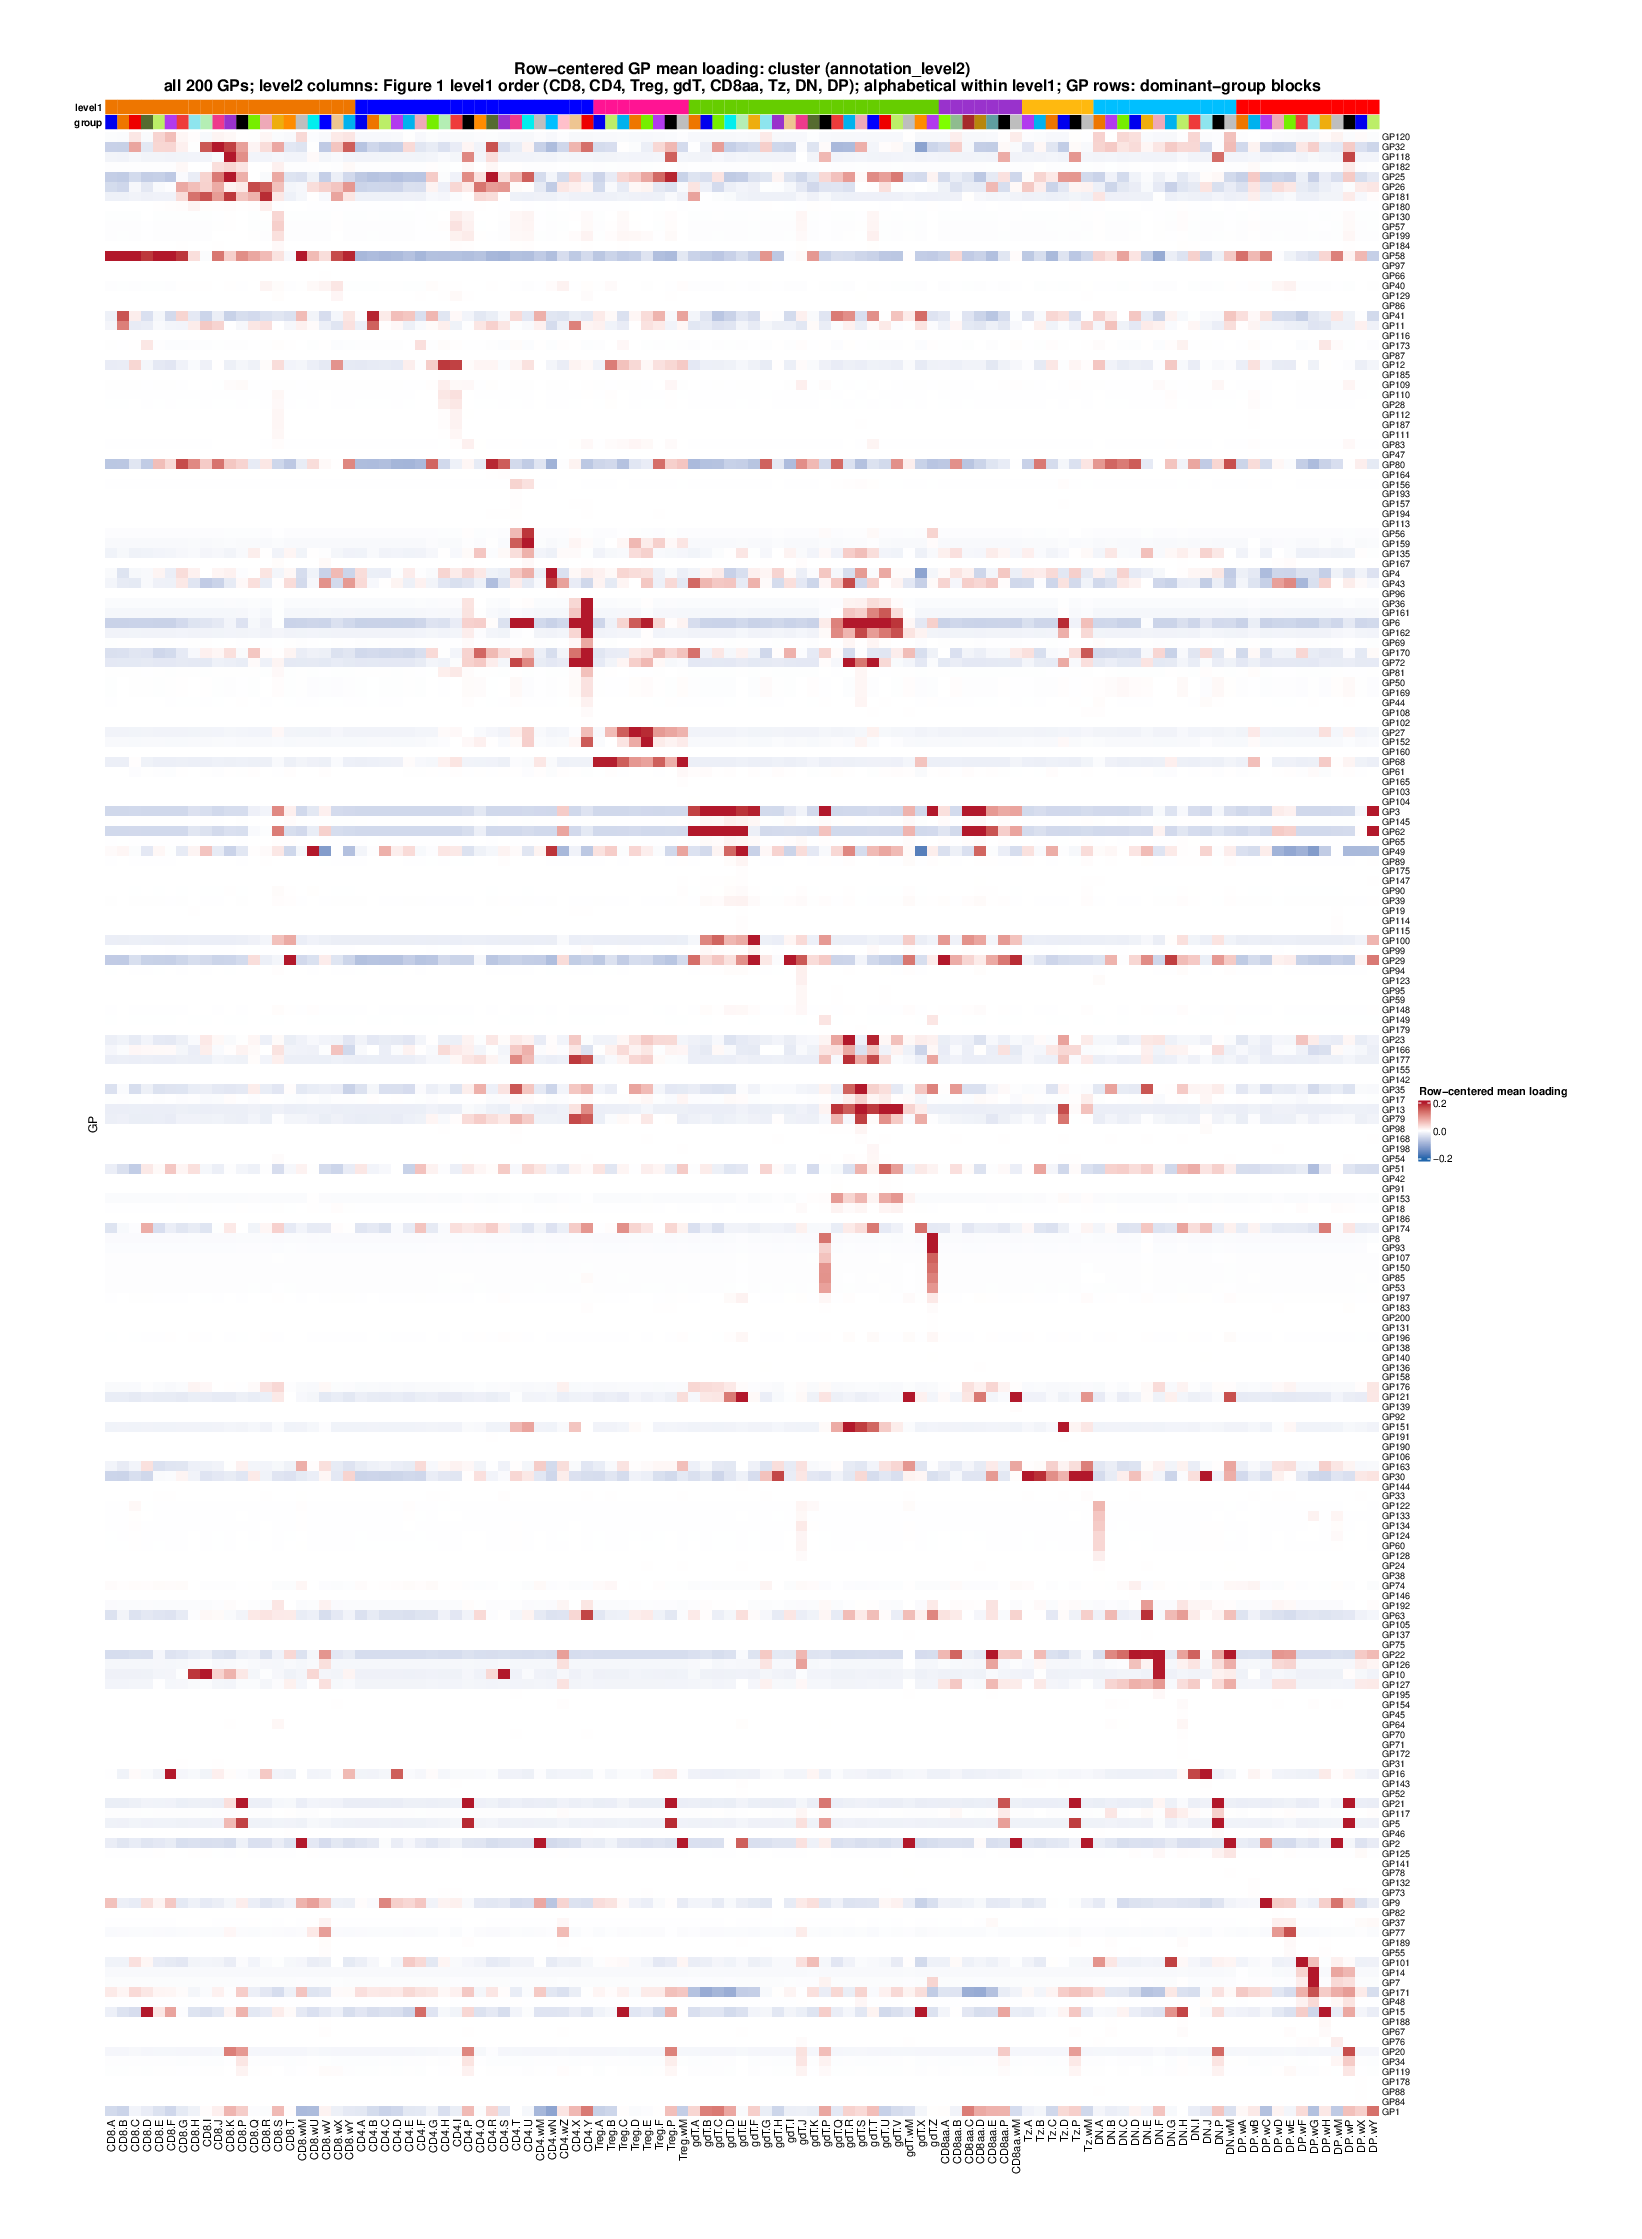
Fig. S4b. Row-centered mean GP activity across the
107 annotation_level2 clusters for all 200 GPs. Columns
follow the lineage order of Figure 3 – the
same level1 sequence as the Figure 1D heatmap (CD8,
CD4, Treg, gdT,
CD8aa, Tz, DN, then
DP) – and are alphabetized within each level1 block. GPs
are arranged into dominant-level2 blocks. The colored top strips
annotate level1 and level2 identity, and the centered color scale is
fixed at -0.2 to 0.2.
Panel rendering
render_centered_heatmap(
  organ_centered,
  organ_palette,
  "tissue (organ_simplified)",
  file.path(figure_path, "s4a.pdf"),
  organ_order$row_order,
  organ_order$column_order,
  centered_color_limit,
  "all 200 GPs; dominant-group blocks (within block: dominance gap)"
)

render_centered_heatmap(
  level2_centered,
  level2_palette,
  "cluster (annotation_level2)",
  file.path(figure_path, "s4b.pdf"),
  level2_order$row_order,
  level2_order$column_order,
  centered_color_limit,
  paste0(
    "all 200 GPs; level2 columns: Figure 1 level1 order ",
    "(CD8, CD4, Treg, gdT, CD8aa, Tz, DN, DP); ",
    "alphabetical within level1; GP rows: dominant-group blocks"
  ),
  group_level1 = level2_group_level1,
  level1_palette = level1_palette
)

summary_dir <- "output/FigureS4"   # build intermediate (not a manuscript panel)
dir.create(summary_dir, recursive = TRUE, showWarnings = FALSE)
write.csv(
  data.frame(
    panel = c("S4a", "S4b"),
    grouping = c("organ_simplified", "annotation_level2"),
    view = "full row-centered mean loading",
    gp_count = c(nrow(organ_centered), nrow(level2_centered)),
    group_count = c(ncol(organ_centered), ncol(level2_centered)),
    centered_definition = "group mean minus mean across groups for each GP",
    color_min = -centered_color_limit,
    color_mid = 0,
    color_max = centered_color_limit,
    observed_min = c(min(organ_centered), min(level2_centered)),
    observed_max = c(max(organ_centered), max(level2_centered))
  ),
  file.path(summary_dir, "S4_summary.csv"),
  row.names = FALSE,
  quote = FALSE
)

message("Wrote final full-centered Figure S4 heatmaps to ", normalizePath(figure_path))
sessionInfo()R version 4.5.1 (2025-06-13)
Platform: aarch64-apple-darwin20
Running under: macOS Sequoia 15.6.1
Matrix products: default
BLAS: /System/Library/Frameworks/Accelerate.framework/Versions/A/Frameworks/vecLib.framework/Versions/A/libBLAS.dylib
LAPACK: /Library/Frameworks/R.framework/Versions/4.5-arm64/Resources/lib/libRlapack.dylib; LAPACK version 3.12.1
locale:
[1] en_CA/en_CA/en_CA/C/en_CA/en_CA
time zone: America/Chicago
tzcode source: internal
attached base packages:
[1] stats graphics grDevices utils datasets methods base
loaded via a namespace (and not attached):
[1] vctrs_0.7.3 cli_3.6.6 knitr_1.50 rlang_1.2.0
[5] xfun_0.55 stringi_1.8.7 otel_0.2.0 promises_1.5.0
[9] jsonlite_2.0.0 workflowr_1.7.2 glue_1.8.1 rprojroot_2.1.1
[13] git2r_0.36.2 htmltools_0.5.9 httpuv_1.6.16 sass_0.4.10
[17] rmarkdown_2.30 evaluate_1.0.5 jquerylib_0.1.4 tibble_3.3.0
[21] fastmap_1.2.0 yaml_2.3.12 lifecycle_1.0.5 whisker_0.4.1
[25] stringr_1.6.0 compiler_4.5.1 fs_1.6.6 Rcpp_1.1.1-1.1
[29] pkgconfig_2.0.3 later_1.4.4 digest_0.6.39 R6_2.6.1
[33] pillar_1.11.1 magrittr_2.0.5 bslib_0.9.0 tools_4.5.1
[37] cachem_1.1.0